docs: add use-my-browser skill and format markdown
This commit is contained in:
 xixu-me committed
1 parent
da6e657a3e
commit
ce1dee0d58
20 files changed
+1823
-855
No files matched your search
@@ -47,20 +47,20 @@ npx skills add xixu-me/skills
|
||||
|
||||
The table below lists the skills maintained in this repository.
|
||||
|
||||
| Name | Description | Bundled Assets |
|
||||
| ------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ------------------------- |
|
||||
| [`develop-userscripts`](./skills/develop-userscripts/SKILL.md) | Build, debug, package, and publish browser userscripts for Tampermonkey and ScriptCat, including ScriptCat background, cron, config, and subscription workflows. | `references/` |
|
||||
| [`github-actions-docs`](./skills/github-actions-docs/SKILL.md) | Write, migrate, secure, and troubleshoot GitHub Actions workflows with official docs. | `references/` |
|
||||
| [`openclaw-secure-linux-cloud`](./skills/openclaw-secure-linux-cloud/SKILL.md) | Securely self-host OpenClaw on cloud servers. | `references/` |
|
||||
| [`opensource-guide-coach`](./skills/opensource-guide-coach/SKILL.md) | Start, grow, govern, fund, and sustain open source projects. | `references/` |
|
||||
| [`readme-i18n`](./skills/readme-i18n/SKILL.md) | Translate repository READMEs, maintain localized variants, and add a language selector without breaking Markdown mechanics. | `references/` |
|
||||
| [`running-claude-code-via-litellm-copilot`](./skills/running-claude-code-via-litellm-copilot/SKILL.md) | Route Claude Code through LiteLLM and GitHub Copilot, including setup and troubleshooting. | `references/` |
|
||||
| [`secure-linux-web-hosting`](./skills/secure-linux-web-hosting/SKILL.md) | Harden cloud servers and web hosting for DNS, SSH, reverse proxies, HTTPS, and safe self-hosting. | `references/` |
|
||||
| [`skills-cli`](./skills/skills-cli/SKILL.md) | Discover, install, list, back up, restore, sync, and manage Agent Skills. | None |
|
||||
| [`tzst`](./skills/tzst/SKILL.md) | Create, extract, list, test, install, and script `tzst` CLI workflows for `.tzst` archives safely. | `references/` |
|
||||
| [`use-my-browser`](./skills/use-my-browser/README.md) | Operate the user's current browser session, continue from DevTools context, and route web tasks across public-web tools, the live browser session, and clean browser contexts. | `references/` |
|
||||
| [`xdrop`](./skills/xdrop/SKILL.md) | Upload to and download from Xdrop through the terminal, including encrypted share-link workflows. | `scripts/` |
|
||||
| [`xget`](./skills/xget/SKILL.md) | Configure and apply Xget acceleration to URLs, package managers, registries, containers, CI, and AI SDKs. | `references/`, `scripts/` |
|
||||
| Name | Description | Bundled Assets |
|
||||
| ------------------------------------------------------------------------------------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------- |
|
||||
| [`develop-userscripts`](./skills/develop-userscripts/SKILL.md) | Build, debug, package, and publish browser userscripts for Tampermonkey and ScriptCat, including ScriptCat background, cron, config, and subscription workflows. | `references/` |
|
||||
| [`github-actions-docs`](./skills/github-actions-docs/SKILL.md) | Write, migrate, secure, and troubleshoot GitHub Actions workflows with official docs. | `references/` |
|
||||
| [`openclaw-secure-linux-cloud`](./skills/openclaw-secure-linux-cloud/SKILL.md) | Securely self-host OpenClaw on cloud servers. | `references/` |
|
||||
| [`opensource-guide-coach`](./skills/opensource-guide-coach/SKILL.md) | Start, grow, govern, fund, and sustain open source projects. | `references/` |
|
||||
| [`readme-i18n`](./skills/readme-i18n/SKILL.md) | Translate repository READMEs, maintain localized variants, and add a language selector without breaking Markdown mechanics. | `references/` |
|
||||
| [`running-claude-code-via-litellm-copilot`](./skills/running-claude-code-via-litellm-copilot/SKILL.md) | Route Claude Code through LiteLLM and GitHub Copilot, including setup and troubleshooting. | `references/` |
|
||||
| [`secure-linux-web-hosting`](./skills/secure-linux-web-hosting/SKILL.md) | Harden cloud servers and web hosting for DNS, SSH, reverse proxies, HTTPS, and safe self-hosting. | `references/` |
|
||||
| [`skills-cli`](./skills/skills-cli/SKILL.md) | Discover, install, list, back up, restore, sync, and manage Agent Skills. | None |
|
||||
| [`tzst`](./skills/tzst/SKILL.md) | Create, extract, list, test, install, and script `tzst` CLI workflows for `.tzst` archives safely. | `references/` |
|
||||
| [`use-my-browser`](./skills/use-my-browser/SKILL.md) | Use the user's live browser session when work depends on rendered state, logged-in flows, uploads, media, DOM inspection, or browser-only failures. | `references/` |
|
||||
| [`xdrop`](./skills/xdrop/SKILL.md) | Upload to and download from Xdrop through the terminal, including encrypted share-link workflows. | `scripts/` |
|
||||
| [`xget`](./skills/xget/SKILL.md) | Configure and apply Xget acceleration to URLs, package managers, registries, containers, CI, and AI SDKs. | `references/`, `scripts/` |
|
||||
|
||||
## Repository Layout
|
||||
|
||||
|
||||
+14
-14
@@ -47,20 +47,20 @@ npx skills add xixu-me/skills
|
||||
|
||||
下表列出了此存储库中维护的 skills。
|
||||
|
||||
| 名称 | 说明 | 附带资源 |
|
||||
| ------------------------------------------------------------------------------------------------------ | -------------------------------------------------------------------------------------------------------------------------- | ------------------------- |
|
||||
| [`develop-userscripts`](./skills/develop-userscripts/SKILL.md) | 为 Tampermonkey 和 ScriptCat 编写、调试、打包并发布浏览器 userscripts,包括 ScriptCat 的后台、定时、用户配置和订阅工作流。 | `references/` |
|
||||
| [`github-actions-docs`](./skills/github-actions-docs/SKILL.md) | 基于官方文档编写、迁移、加固并排查 GitHub Actions workflows。 | `references/` |
|
||||
| [`openclaw-secure-linux-cloud`](./skills/openclaw-secure-linux-cloud/SKILL.md) | 在云服务器上安全地自托管 OpenClaw。 | `references/` |
|
||||
| [`opensource-guide-coach`](./skills/opensource-guide-coach/SKILL.md) | 启动、发展、治理、资助并长期维护开源项目。 | `references/` |
|
||||
| [`readme-i18n`](./skills/readme-i18n/SKILL.md) | 翻译存储库 README、维护多语言 README 变体,并在不破坏 Markdown 结构的前提下添加语言切换器。 | `references/` |
|
||||
| [`running-claude-code-via-litellm-copilot`](./skills/running-claude-code-via-litellm-copilot/SKILL.md) | 通过 LiteLLM 和 GitHub Copilot 路由 Claude Code,并完成安装配置与排障。 | `references/` |
|
||||
| [`secure-linux-web-hosting`](./skills/secure-linux-web-hosting/SKILL.md) | 加固云服务器与网站托管的 DNS、SSH、反向代理、HTTPS 和安全自托管配置。 | `references/` |
|
||||
| [`skills-cli`](./skills/skills-cli/SKILL.md) | 发现、安装、列出、备份、恢复、同步并管理 Agent Skills。 | 无 |
|
||||
| [`tzst`](./skills/tzst/SKILL.md) | 安全地创建、解压、列出、校验、安装并脚该化 `tzst` CLI 的 `.tzst` 档案工作流。 | `references/` |
|
||||
| [`use-my-browser`](./skills/use-my-browser/README.zh.md) | 操作用户当前的浏览器会话、承接 DevTools 上下文,并在公共网页工具、实时浏览器会话和干净浏览器上下文之间路由网页任务。 | `references/` |
|
||||
| [`xdrop`](./skills/xdrop/SKILL.md) | 通过终端上传到和下载自 Xdrop,并处理加密分享链接工作流。 | `scripts/` |
|
||||
| [`xget`](./skills/xget/SKILL.md) | 将 Xget 加速能力应用到 URL、包管理器、存储库、容器、CI 和 AI SDK 等场景。 | `references/`, `scripts/` |
|
||||
| 名称 | 说明 | 附带资源 |
|
||||
| ------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------ | ------------------------- |
|
||||
| [`develop-userscripts`](./skills/develop-userscripts/SKILL.md) | 为 Tampermonkey 和 ScriptCat 编写、调试、打包并发布浏览器 userscripts,包括 ScriptCat 的后台、定时、用户配置和订阅工作流。 | `references/` |
|
||||
| [`github-actions-docs`](./skills/github-actions-docs/SKILL.md) | 基于官方文档编写、迁移、加固并排查 GitHub Actions workflows。 | `references/` |
|
||||
| [`openclaw-secure-linux-cloud`](./skills/openclaw-secure-linux-cloud/SKILL.md) | 在云服务器上安全地自托管 OpenClaw。 | `references/` |
|
||||
| [`opensource-guide-coach`](./skills/opensource-guide-coach/SKILL.md) | 启动、发展、治理、资助并长期维护开源项目。 | `references/` |
|
||||
| [`readme-i18n`](./skills/readme-i18n/SKILL.md) | 翻译存储库 README、维护多语言 README 变体,并在不破坏 Markdown 结构的前提下添加语言切换器。 | `references/` |
|
||||
| [`running-claude-code-via-litellm-copilot`](./skills/running-claude-code-via-litellm-copilot/SKILL.md) | 通过 LiteLLM 和 GitHub Copilot 路由 Claude Code,并完成安装配置与排障。 | `references/` |
|
||||
| [`secure-linux-web-hosting`](./skills/secure-linux-web-hosting/SKILL.md) | 加固云服务器与网站托管的 DNS、SSH、反向代理、HTTPS 和安全自托管配置。 | `references/` |
|
||||
| [`skills-cli`](./skills/skills-cli/SKILL.md) | 发现、安装、列出、备份、恢复、同步并管理 Agent Skills。 | 无 |
|
||||
| [`tzst`](./skills/tzst/SKILL.md) | 安全地创建、解压、列出、校验、安装并脚该化 `tzst` CLI 的 `.tzst` 档案工作流。 | `references/` |
|
||||
| [`use-my-browser`](./skills/use-my-browser/SKILL.md) | 当工作依赖用户当前浏览器里的渲染结果、登录态流程、上传下载、媒体内容、DOM 检查或仅在浏览器中出现的故障时,使用用户的实时浏览器会话。 | `references/` |
|
||||
| [`xdrop`](./skills/xdrop/SKILL.md) | 通过终端上传到和下载自 Xdrop,并处理加密分享链接工作流。 | `scripts/` |
|
||||
| [`xget`](./skills/xget/SKILL.md) | 将 Xget 加速能力应用到 URL、包管理器、存储库、容器、CI 和 AI SDK 等场景。 | `references/`, `scripts/` |
|
||||
|
||||
## 存储库结构
|
||||
|
||||
|
||||
+184
-121
@@ -1,71 +1,153 @@
|
||||
# Use My Browser
|
||||
# `use-my-browser` skill
|
||||
|
||||
**_[汉语](./README.zh.md)_**
|
||||
**_[汉语](README.zh.md)_**
|
||||
|
||||
`use-my-browser` is a browser automation strategy skill for agents that need to operate the user's current browser session, inspect pages, continue from DevTools context, debug dynamic apps, work with logged-in websites, and extract media from rendered pages; it also teaches the agent when a browser is actually needed and when to route the task through public-web tools, the live Chrome session, raw fetches, or a clean browser context.
|
||||
`use-my-browser` is a strategy-first skill for agents that need evidence from the user's live browser session rather than from static retrieval alone. Use it when the browser itself is the evidence: a logged-in dashboard, a localhost app, a dynamic or lazy-loaded page, a rendered-state UX review, or an active DevTools context such as a selected request or element.
|
||||
|
||||
> [!IMPORTANT]
|
||||
> This skill is especially useful when browser automation is part of the job, but the agent still needs judgment about whether to use public-web tools, the live Chrome session, raw fetches, or a clean browser context.
|
||||
Inspired by [`web-access`](https://github.com/eze-is/web-access), this skill is a specialized refactor for the Chrome DevTools MCP era. It is designed as a browser-session strategy layer for live debugging, not as a generic browsing default or a replacement for ordinary static retrieval.
|
||||
|
||||
## Why This Skill Exists
|
||||
## When to Use This Skill
|
||||
|
||||
Web tasks often look like "just open the browser," but in practice they split into very different automation jobs: some need the user's logged-in Chrome session, some need DevTools inspection of the live DOM or network, some are safer in a clean browser context, and some do not need browser automation at all. This skill exists to help the agent handle browser-driven work deliberately: continue from the user's existing browser state when helpful, extract evidence from the page before guessing, and avoid unnecessary disruption while still choosing the right layer for the task.
|
||||
Use this skill when the answer depends on live browser state, for example:
|
||||
|
||||
## Capabilities
|
||||
- a page is already authenticated in the user's current browser session
|
||||
- the rendered UI is the evidence, such as above-the-fold layout, visible confirmation, or lazy-loaded content
|
||||
- the workflow depends on in-browser interaction, such as uploads, drag-and-drop, hover states, or rich text entry
|
||||
- the user already has useful DevTools context open, such as a selected request or element
|
||||
- the target is a localhost app or another page where browser state is easier to trust than URL guessing
|
||||
|
||||
This skill helps an agent do the following:
|
||||
Prefer a static path instead when a stable URL plus direct retrieval can already answer the question. This skill is intentionally not the default for ordinary web fetching.
|
||||
|
||||
| Capability | What It Means |
|
||||
| --------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
|
||||
| Smart Tool Routing | The agent can choose between public web search, processed reads, raw fetches, shell-based fetches, and live browser tooling based on the task instead of forcing everything through one path. |
|
||||
| Live Chrome Control | The agent can attach to the user's current Chrome session when login state, cookies, current app context, or a selected DevTools target matters. |
|
||||
| DevTools-Driven Interaction | The agent can inspect and operate on dynamic pages using DOM reads, clicks, form fills, uploads, console inspection, network inspection, performance tooling, and screenshots when needed. |
|
||||
| DevTools Handoff | If the user already selected an element in Elements or a request in Network, the agent can continue from that exact context instead of reproducing the issue from scratch. |
|
||||
| Evidence-First Inspection | The agent prefers snapshots, DOM reads, console output, network requests, and direct extraction before falling back to screenshots or repetitive UI interaction. |
|
||||
| Media Extraction | The agent can pull image or video URLs from the page directly, inspect media state, and use rendered screenshots only when pixel-level evidence is actually needed. |
|
||||
| Parallel Research | For independent targets, the agent can batch public-web work and structure comparisons across multiple sites more efficiently, while avoiding parallel work that depends on one mutable page state. |
|
||||
| Isolated Browser Fallback | When the task needs a clean browser context, or the live Chrome session is unavailable, the agent can switch to a separate automation browser instead of forcing everything through the user's current session. |
|
||||
| Site Memory | The skill supports storing validated per-domain notes such as URL patterns, platform traits, extraction tactics, and known traps for reuse in later sessions. |
|
||||
| Safe Escalation | The agent can start with the cheapest path that might work, escalate only when needed, and avoid disturbing the user's live browser session unless the task truly requires it. |
|
||||
## Example Prompts
|
||||
|
||||
## Example Uses
|
||||
Examples are easiest to understand when grouped by intent.
|
||||
|
||||
Examples are easiest to understand when grouped by intent:
|
||||
|
||||
**Logged-in browser actions**
|
||||
### Logged-in browser actions
|
||||
|
||||
- "Post this video on YouTube and leave the last click to me."
|
||||
- "Check this logged-in dashboard without making me sign in again."
|
||||
|
||||
**Website inspection and UX review**
|
||||
### Website inspection and UX review
|
||||
|
||||
- `Visit the page https://xi-xu.me and see how its UX design is`
|
||||
- `Compare these public sources, cite them, and only use the browser if the static path fails`
|
||||
- "Visit the Chrome Developers homepage and review its UX and visual design."
|
||||
- "Compare these public sources, cite them, and only use the browser if the static path fails."
|
||||
- "Open this pricing page and tell me what the user actually sees above the fold."
|
||||
|
||||
**Social and dynamic site research**
|
||||
### Local app and localhost debugging
|
||||
|
||||
- `Go to X.com and search for Xi Xu's account to see what he has recently posted`
|
||||
- `Pull the real image or video source from this lazy-loaded page`
|
||||
- "Open my localhost app, reproduce the broken upload flow, and tell me why it silently fails."
|
||||
- "Inspect this local dashboard and confirm whether the saved state is actually visible after publishing."
|
||||
|
||||
**DevTools handoff**
|
||||
### Social and dynamic site research
|
||||
|
||||
- `I already have the failing request selected in DevTools. Explain why it returns 403`
|
||||
- `I clicked into the broken element in Elements. Figure out why the layout is wrong`
|
||||
- "Go to X.com and find this company's account to see what it has posted recently."
|
||||
- "Pull the real image or video source from this lazy-loaded page."
|
||||
- "Inspect this infinite-scroll page and extract the actual links it reveals in the rendered UI."
|
||||
|
||||
**Parallel comparison work**
|
||||
### DevTools-context handoff
|
||||
|
||||
- `Research the websites of these 5 projects simultaneously and provide a comparative summary`
|
||||
- `Compare these three product pages and tell me how their onboarding flows differ`
|
||||
- "I already have the failing request selected in DevTools. Explain why it returns 403."
|
||||
- "I clicked into the broken element in Elements. Figure out why the layout is wrong."
|
||||
|
||||
### Parallel comparison work
|
||||
|
||||
- "Research the websites of these five projects simultaneously and provide a comparative summary."
|
||||
- "Compare these three product pages and tell me how their onboarding flows differ."
|
||||
|
||||
## Why This Skill Exists
|
||||
|
||||
The core idea comes from the newer Chrome DevTools MCP workflow described in [Let your Coding Agent debug your browser session with Chrome DevTools MCP](https://developer.chrome.com/blog/chrome-devtools-mcp-debug-your-browser-session):
|
||||
|
||||
- coding agents can reuse an existing browser session instead of forcing a second sign-in
|
||||
- coding agents can take over an active debugging context, such as a selected request in Network or a selected element in Elements
|
||||
- manual debugging and AI-assisted debugging can now flow into each other instead of living in separate browser sessions
|
||||
|
||||
That changes the job of a browser skill.
|
||||
|
||||
Broader browser-toolbox skills are often built around transport: search, fetch, `curl`, CDP, and site-specific tricks all bundled into one place. That is useful, but live-session debugging has a different center of gravity. Once an agent can attach to the browser you are already using, the hard part is no longer only "how do I reach the page?" It becomes:
|
||||
|
||||
- when should the agent stay on a static path versus take over the live browser?
|
||||
- how should it continue from the current page or selected DevTools context instead of reproducing from scratch?
|
||||
- how should it prove that browser capability is really available before it mutates anything?
|
||||
- how should it recover from stale page state, rerenders, ambiguous saves, and stale action targets?
|
||||
- how should it preserve reusable site knowledge without turning that knowledge into stale superstition?
|
||||
|
||||
`use-my-browser` exists to answer those questions.
|
||||
|
||||
## Capabilities
|
||||
|
||||
The skill is organized around the situations that become important once a coding agent can connect to the user's current browser session.
|
||||
|
||||
### Goal-first routing
|
||||
|
||||
- Classifies each task as `static-capable` or `browser-required`
|
||||
- Keeps static tasks on the cheapest path that still produces the right evidence
|
||||
- Prevents silent downgrade once a task truly depends on live browser state
|
||||
|
||||
### Live-session browser work
|
||||
|
||||
- Reuses the user's current browser session when that session is the real source of truth
|
||||
- Treats rendered UI, visible confirmation, login state, lazy-loaded content, and browser-only structures as first-class evidence
|
||||
- Prefers MCP-native browser actions over script-heavy improvisation when the task is truly in-browser
|
||||
|
||||
### Rendered-state inspection and UX review
|
||||
|
||||
- Supports review of what the page visibly shows, not just what static HTML or extracted text suggests
|
||||
- Fits UX inspection, above-the-fold review, layout confirmation, and other tasks where rendered state is the evidence
|
||||
- Escalates into the browser only when the visible experience matters more than a static extract
|
||||
|
||||
### DevTools handoff
|
||||
|
||||
- Starts from the current debugging context when the user already has the page, element, or request open
|
||||
- Supports handoff from selected Elements and selected Network requests
|
||||
- Avoids replaying an entire repro flow when the browser already contains the clue
|
||||
|
||||
### Control-plane safety
|
||||
|
||||
- Adds stronger confirmation discipline for save, publish, upload, and settings workflows
|
||||
- Separates read-only inspection from state-changing actions
|
||||
- Requires visible and structural proof before claiming a state change succeeded
|
||||
- Supports stopping before the final high-risk mutation when the user wants the last click or publish step to remain manual
|
||||
|
||||
### Deep DOM and media inspection
|
||||
|
||||
- Handles Shadow DOM, iframe, collapsed content, lazy-loaded content, and rendered-only evidence
|
||||
- Uses DOM-level inspection only when snapshots are insufficient
|
||||
- Distinguishes between extracting the real media source and inspecting the rendered media state
|
||||
|
||||
### Selector-to-MCP bridging
|
||||
|
||||
- Bridges known selectors into MCP-native `uid` targets
|
||||
- Helps preserve real browser interaction even when the a11y tree does not directly expose the target you need
|
||||
- Improves upload and action targeting without rebuilding a custom executor
|
||||
|
||||
### Recovery and ambiguity handling
|
||||
|
||||
- Responds to stale `uid`s, unexpected navigation, ambiguous results, and interaction failures with a defined recovery loop
|
||||
- Escalates to console or network inspection only when that evidence can change the next action
|
||||
- Stops cleanly when capability or page ownership becomes ambiguous
|
||||
|
||||
### Reusable site knowledge
|
||||
|
||||
- Stores verified site-specific operating facts under `references/site-patterns/`
|
||||
- Treats site knowledge as operational evidence, not folklore
|
||||
- Explicitly supports downgrading or removing stale claims when a site pattern stops working
|
||||
|
||||
### Parallel browser ownership
|
||||
|
||||
- Supports multi-page and multi-agent work without page collisions
|
||||
- Defines one-owner-per-page discipline
|
||||
- Makes cleanup and page ownership explicit instead of implicit
|
||||
|
||||
## Installation
|
||||
|
||||
Install this skill with the `skills` CLI:
|
||||
Install this skill with the [`skills` CLI](https://github.com/vercel-labs/skills):
|
||||
|
||||
```bash
|
||||
bunx skills add xixu-me/skills -s use-my-browser
|
||||
```
|
||||
|
||||
If Bun is not available, use `npx`:
|
||||
If Bun is not available, use npm:
|
||||
|
||||
```bash
|
||||
npx skills add xixu-me/skills -s use-my-browser
|
||||
@@ -73,27 +155,31 @@ npx skills add xixu-me/skills -s use-my-browser
|
||||
|
||||
## Prerequisites
|
||||
|
||||
This skill works best when the agent can reuse your current Chrome session through Chrome DevTools MCP. For live browser automation, set up Chrome remote debugging first, then configure the MCP server to attach automatically to the running browser.
|
||||
|
||||
> [!IMPORTANT]
|
||||
> Make sure Chrome is already running before you start. Otherwise, the agent may be unable to attach to your current browser session and may fall back to a separate isolated browser session instead.
|
||||
|
||||
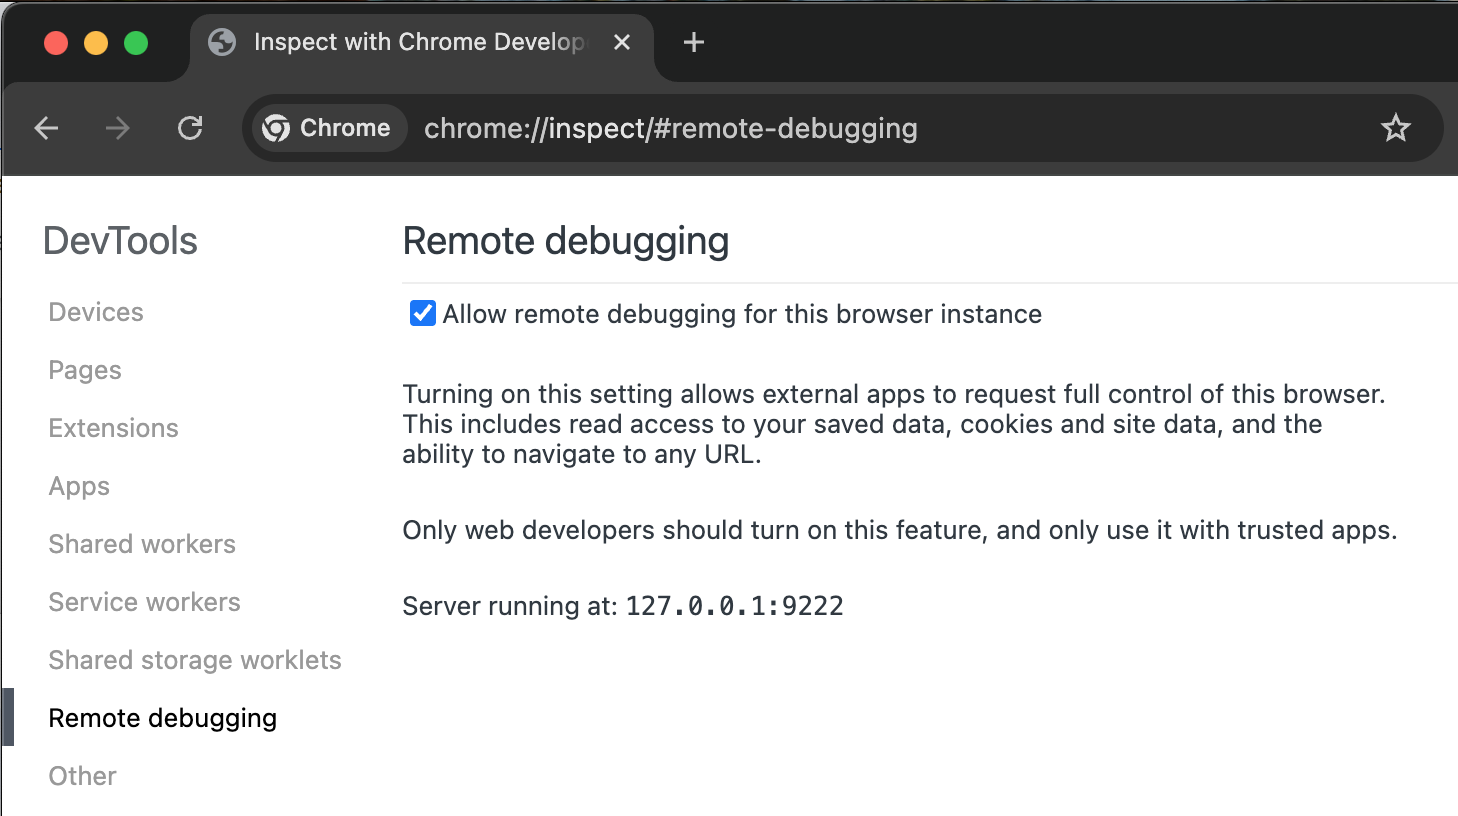
In Chrome (>=144), navigate to `chrome://inspect/#remote-debugging` to enable remote debugging.
|
||||
For the automatic live-session flow described in the [Chrome DevTools MCP README](https://github.com/ChromeDevTools/chrome-devtools-mcp?tab=readme-ov-file#automatically-connecting-to-a-running-chrome-instance):
|
||||
|
||||
1. In Chrome (`>=144`), navigate to `chrome://inspect/#remote-debugging` to enable remote debugging.
|
||||
2. Keep Chrome running.
|
||||
3. Configure Chrome DevTools MCP with `--autoConnect`.
|
||||
|
||||
|
||||
|
||||
To connect the Chrome DevTools MCP server to the running Chrome instance, use the `--autoConnect` command line argument in the MCP server configuration.
|
||||
|
||||
You can run it with either Bun or npm:
|
||||
The default examples below use Bun. If you prefer npm, an `npx` variant is included right after.
|
||||
|
||||
```bash
|
||||
bunx chrome-devtools-mcp@latest --autoConnect --no-usage-statistics
|
||||
bunx chrome-devtools-mcp@latest --autoConnect
|
||||
```
|
||||
|
||||
```bash
|
||||
npx chrome-devtools-mcp@latest --autoConnect --no-usage-statistics
|
||||
npx chrome-devtools-mcp@latest --autoConnect
|
||||
```
|
||||
|
||||
If you want to opt out of Chrome DevTools MCP usage statistics, add `--no-usage-statistics` to either command or configuration example below.
|
||||
|
||||
If the MCP server runs in a sandbox or on a different machine than the browser, use a manual connection such as `--browserUrl=http://127.0.0.1:9222` instead of `--autoConnect`. That manual route requires Chrome to be started with a remote debugging port; see the [Chrome DevTools MCP README](https://github.com/ChromeDevTools/chrome-devtools-mcp?tab=readme-ov-file#manual-connection-using-port-forwarding) for the platform-specific launch command.
|
||||
|
||||
Many agent runtimes use a JSON-style MCP configuration like this:
|
||||
|
||||
```json
|
||||
@@ -101,11 +187,7 @@ Many agent runtimes use a JSON-style MCP configuration like this:
|
||||
"mcpServers": {
|
||||
"chrome-devtools": {
|
||||
"command": "bunx",
|
||||
"args": [
|
||||
"chrome-devtools-mcp@latest",
|
||||
"--autoConnect",
|
||||
"--no-usage-statistics"
|
||||
]
|
||||
"args": ["chrome-devtools-mcp@latest", "--autoConnect"]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -116,95 +198,76 @@ For Codex, the MCP configuration can look like this:
|
||||
```toml
|
||||
[mcp_servers.chrome-devtools]
|
||||
command = "bunx"
|
||||
args = ["chrome-devtools-mcp@latest", "--autoConnect", "--no-usage-statistics"]
|
||||
args = ["chrome-devtools-mcp@latest", "--autoConnect"]
|
||||
```
|
||||
|
||||
## Strategy Model
|
||||
> [!TIP]
|
||||
> During an active Chrome DevTools MCP debugging session, it is normal for Chrome to ask for permission first and then show the "Chrome is being controlled by automated test software" banner while the session is active.
|
||||
|
||||
This skill is not just a bundle of browser tricks. It teaches a browsing strategy.
|
||||
## Strategy Layer
|
||||
|
||||
### 1. Define success before choosing tools
|
||||
The strategy is intentionally simple:
|
||||
|
||||
The agent starts with the goal, not the tool. It first determines whether the task is citation-heavy, interaction-heavy, debugging-heavy, or dependent on the user's current browser state.
|
||||
1. Decide whether the task is `static-capable` or `browser-required`.
|
||||
2. Use the cheapest route that can still produce the evidence the user actually needs.
|
||||
3. If the task is `browser-required`, stay on the browser path instead of silently downgrading.
|
||||
4. If the user already has a live debugging context, continue from that context before attempting a fresh repro.
|
||||
5. Before finishing, decide whether the run produced reusable site knowledge or disproved an old assumption.
|
||||
|
||||
### 2. Start with the cheapest layer that can succeed
|
||||
This is the main distinction from broader networking skills.
|
||||
|
||||
The default routing model is:
|
||||
In practice, this means:
|
||||
|
||||
1. public web search and page reads
|
||||
2. processed content reads
|
||||
3. raw fetches for source HTML, headers, or direct assets
|
||||
4. live Chrome DevTools session
|
||||
5. clean browser automation
|
||||
- `localhost`, local dashboards, uploads, drag-and-drop flows, and save/publish confirmation are usually `browser-required`
|
||||
- public pages with stable URLs and small extraction goals usually stay on the static path
|
||||
- high-risk control-plane work can stop before the final mutation if the user wants to keep the last action manual
|
||||
|
||||
This is an escalation model, not a rigid ladder. If the task obviously depends on the current signed-in browser state, the agent should start with the live session.
|
||||
## How It Works
|
||||
|
||||
### 3. Treat each result as evidence
|
||||
The skill is structured as one entrypoint plus focused references:
|
||||
|
||||
Each step should update the plan. Search results, snapshots, requests, console logs, and screenshots are evidence, not ceremony. The skill encourages agents to stop repeating failed tactics and to switch layers when the current one is no longer informative.
|
||||
- [`SKILL.md`](./SKILL.md): entrypoint, scope, task classification, hard rules, and reference loading guide
|
||||
- [`references/task-routing.md`](./references/task-routing.md): static retrieval versus live browser routing
|
||||
- [`references/browser-playbook.md`](./references/browser-playbook.md): default live-browser operating loop
|
||||
- [`references/browser-capability-matrix.md`](./references/browser-capability-matrix.md): prove browser capability with real browser-tool calls
|
||||
- [`references/debug-handoff.md`](./references/debug-handoff.md): continue from the user's active DevTools context
|
||||
- [`references/control-plane-workflows.md`](./references/control-plane-workflows.md): safer save, publish, upload, and update workflows
|
||||
- [`references/anti-automation-friction.md`](./references/anti-automation-friction.md): soft 404s, auth walls, suspicious no-op interactions, and anti-automation friction
|
||||
- [`references/deep-dom.md`](./references/deep-dom.md): iframe, Shadow DOM, collapsed content, and lazy-loaded evidence
|
||||
- [`references/media-inspection.md`](./references/media-inspection.md): real media source extraction and rendered media inspection
|
||||
- [`references/parallel-browser-ownership.md`](./references/parallel-browser-ownership.md): multi-page and multi-agent browser ownership
|
||||
- [`references/selector-bridge.md`](./references/selector-bridge.md): convert selector knowledge into MCP-native action targets
|
||||
- [`references/browser-recovery.md`](./references/browser-recovery.md): recover from stale targets, rerenders, and ambiguous UI state
|
||||
- [site-pattern maintenance rules](./references/site-patterns/README.md): rules for maintaining domain-specific operating knowledge
|
||||
|
||||
### 4. Preserve the user's browser session
|
||||
The references are intentionally one level deep. The entrypoint decides which document to load next so the protocol stays understandable and composable.
|
||||
|
||||
When using the live browser:
|
||||
## Implementation Details
|
||||
|
||||
- reuse the current page only when its state is actually the point of the task
|
||||
- otherwise open or use a dedicated working tab
|
||||
- avoid closing, reloading, or hijacking tabs the user may still care about
|
||||
- prefer structured extraction over intrusive interaction
|
||||
This skill does not implement a custom browser proxy. It documents a browser-session operating model for MCP-capable agents.
|
||||
|
||||
### 5. Prefer primary sources over recycled summaries
|
||||
Key implementation choices:
|
||||
|
||||
Search is for discovery. Verification should come from primary sources, official docs, direct pages, raw responses, and live-session evidence where needed.
|
||||
- **Capability-first, not tool-first.** The skill proves live-browser capability through real browser-tool calls instead of shell guesses or assumed integration details.
|
||||
- **Session reuse over fresh automation.** The skill assumes the user's current browser session is often the most valuable artifact, especially for logged-in pages and DevTools investigations.
|
||||
- **MCP-native action bias.** The default loop prefers snapshots and MCP-native actions before broad DOM scripting.
|
||||
- **Focused escalation.** `evaluate_script`, console inspection, and network inspection are escalation tools, not the default operating mode.
|
||||
- **Ownership discipline.** Pages created by the task are tracked and cleaned up conservatively; user-owned pages are left alone.
|
||||
- **Experience loop.** Site-specific knowledge is only stored when it is verified and reusable, and it can be downgraded when it becomes stale.
|
||||
|
||||
## How The Skill Implements This
|
||||
This makes the skill more modern than a custom browser automation stack skill in one important way: it is built for the live-session debugging model that Chrome DevTools MCP is moving toward, not just for remote control of a browser tab.
|
||||
|
||||
The skill is split into a main policy file and a small set of focused references:
|
||||
## Relationship to `web-access`
|
||||
|
||||
- [`SKILL.md`](./SKILL.md): the main decision model, safety rules, escalation logic, and examples
|
||||
- [`references/tool-matrix.md`](./references/tool-matrix.md): routing rules for choosing between public web, raw fetches, live browser tooling, and clean browser contexts
|
||||
- [`references/session-playbook.md`](./references/session-playbook.md): session hygiene, login handling, DOM-first extraction, and live-session fallback patterns
|
||||
- [`references/browser-recipes.md`](./references/browser-recipes.md): concrete browser operations and tool mappings
|
||||
- [`references/site-patterns/README.md`](./references/site-patterns/README.md): how to store validated site-specific notes without turning guesses into policy
|
||||
This skill is openly inspired by `web-access`, especially its emphasis on routing by evidence, preserving site knowledge, and treating browser work as a serious operating mode rather than a last-resort hack.
|
||||
|
||||
Together, these files form the skill's "scheduling strategy" layer:
|
||||
The difference is scope. `web-access` is a broader web toolbox; `use-my-browser` narrows the mission to correctly taking over the user's live browser session inside an MCP-native workflow.
|
||||
|
||||
- what to try first
|
||||
- when to escalate
|
||||
- when to switch modes
|
||||
- how to keep independent research tasks separate
|
||||
- how to avoid unnecessary browser intrusion
|
||||
That means:
|
||||
|
||||
## When To Use It
|
||||
- less "all web tasks go here"
|
||||
- more "this is how to operate safely and efficiently inside the user's current browser"
|
||||
- less emphasis on custom browser transport
|
||||
- more emphasis on routing, debugging handoff, confirmation discipline, recovery, and page ownership
|
||||
|
||||
Use this skill when:
|
||||
|
||||
- the user wants web research, page inspection, or browser interaction and tool choice matters
|
||||
- the task depends on the current browser session, cookies, or sign-in state
|
||||
- the user already has the relevant page, DevTools element, or network request open
|
||||
- the target is a dynamic or anti-bot-heavy site where static fetches are unreliable
|
||||
- the task needs DOM, console, network, performance, or rendered-state evidence
|
||||
- you need a deliberate approach to comparing several websites or public sources
|
||||
|
||||
## When Not To Use It
|
||||
|
||||
Do not use this skill when:
|
||||
|
||||
- the task is purely local and does not involve the web
|
||||
- a normal public-web read is already enough and no browser decision is needed
|
||||
- the user explicitly does not want their live browser session touched
|
||||
- the job is purely isolated automation and does not benefit from the live-session routing model
|
||||
|
||||
## What Makes It Different
|
||||
|
||||
Most browser-oriented skills focus on how to drive a browser. This one focuses on when, why, and at what layer to do that.
|
||||
|
||||
That makes it a better fit for agents that need judgment, not just clicks.
|
||||
|
||||
## References
|
||||
|
||||
- [Chrome DevTools MCP](https://github.com/ChromeDevTools/chrome-devtools-mcp)
|
||||
- [Let your Coding Agent debug your browser session with Chrome DevTools MCP](https://developer.chrome.com/blog/chrome-devtools-mcp-debug-your-browser-session)
|
||||
|
||||
## Inspiration
|
||||
|
||||
- [Web Access](https://github.com/eze-is/web-access)
|
||||
Read this skill as a specialized strategy-layer refactor for the live-session debugging paradigm, not as a replacement for `web-access`.
|
||||
+187
-124
@@ -1,71 +1,153 @@
|
||||
# Use My Browser
|
||||
# `use-my-browser` skill
|
||||
|
||||
**_[English](./README.md)_**
|
||||
**_[English](README.md)_**
|
||||
|
||||
`use-my-browser` 是一个浏览器自动化策略 skill,适用于需要操作用户当前的浏览器会话、检查页面、承接 DevTools 上下文、调试动态应用、操作已登录网站以及从渲染后的页面中提取媒体内容的智能体;它还会教会智能体何时真正需要浏览器,以及何时应将任务路由到公共网页工具、实时 Chrome 会话、原始抓取或干净的浏览器上下文。
|
||||
`use-my-browser` 是一个策略优先的 skill,适用于那些需要从用户当前的实时浏览器会话中获取证据,而不是仅依赖静态检索的智能体。当浏览器本身就是证据来源时,就该使用它:例如已登录的控制台、localhost 应用、动态或懒加载页面、基于渲染结果的 UX 审查,或当前处于活动状态的 DevTools 上下文,比如已选中的请求或元素。
|
||||
|
||||
> [!IMPORTANT]
|
||||
> 当任务本身涉及浏览器自动化,但智能体仍需要判断应使用公共网页工具、实时 Chrome 会话、原始抓取还是干净浏览器上下文时,该 skill 尤其有用。
|
||||
它受到 [`web-access`](https://github.com/eze-is/web-access) 的启发,是面向 Chrome DevTools MCP 时代的一次专门化重构。它被设计成用于实时调试的浏览器会话策略层,而不是一个通用浏览默认方案,也不是普通静态检索的替代品。
|
||||
|
||||
## 为什么需要该 skill
|
||||
## 何时使用该 skill
|
||||
|
||||
网页任务常常看起来像是“直接打开浏览器就行”,但在实际中,它们会分化成非常不同的自动化工作:有些需要用户已经登录的 Chrome 会话,有些需要对实时 DOM 或网络请求进行 DevTools 检查,有些在干净的浏览器上下文中会更安全,还有些其实根本不需要浏览器自动化。该 skill 的存在,是为了帮助智能体更有判断地处理这类浏览器驱动任务:在有帮助时延续用户当前的浏览器状态,在猜测之前先从页面提取证据,并在尽量不打扰用户会话的前提下选择合适的层级。
|
||||
当答案依赖于实时浏览器状态时,就应使用该 skill,例如:
|
||||
|
||||
- 页面已经在用户当前的浏览器会话中完成认证
|
||||
- 渲染后的 UI 本身就是证据,例如首屏布局、可见确认信息或懒加载内容
|
||||
- 工作流依赖浏览器内交互,例如上传、拖拽、悬停状态或富文本输入
|
||||
- 用户已经在 DevTools 中打开了有价值的上下文,例如已选中的请求或元素
|
||||
- 目标是 localhost 应用,或其他比起猜测 URL、更适合直接信任浏览器状态的页面
|
||||
|
||||
如果稳定的 URL 加上直接检索已经足以回答问题,就优先走静态路径。该 skill 有意不作为普通网页抓取任务的默认方案。
|
||||
|
||||
## 示例提示词
|
||||
|
||||
按意图分组时,这些示例最容易理解。
|
||||
|
||||
### 已登录的浏览器操作
|
||||
|
||||
- “将该视频发到 YouTube,最后一次点击留给我。”
|
||||
- “检查该已登录的控制台,不要让我再登录一次。”
|
||||
|
||||
### 网站检查与 UX 评审
|
||||
|
||||
- “访问 Chrome Developers 首页,评审它的 UX 和视觉设计。”
|
||||
- “比较这些公开来源,给出引用,只有在静态路径失败时才使用浏览器。”
|
||||
- “打开该定价页面,告诉我用户在首屏真正会看到什么。”
|
||||
|
||||
### 本地应用与 localhost 调试
|
||||
|
||||
- “打开我的 localhost 应用,复现损坏的上传流程,并告诉我为什么它会悄无声息地失败。”
|
||||
- “检查该本地控制台,确认发布后保存的状态是否真的可见。”
|
||||
|
||||
### 社交网站与动态页面研究
|
||||
|
||||
- “去 X.com 找这家公司的账号,看看它最近发了什么。”
|
||||
- “从该懒加载页面里提取真实的图片或视频源地址。”
|
||||
- “检查该无限滚动页面,提取它在渲染后真正显示出来的链接。”
|
||||
|
||||
### DevTools 上下文接力
|
||||
|
||||
- “我已经在 DevTools 里选中了失败的请求。解释一下它为什么返回 403。”
|
||||
- “我已经在 Elements 面板里点到了出问题的元素。找出为什么布局不对。”
|
||||
|
||||
### 并行对比类工作
|
||||
|
||||
- “同时研究这五个项目的网站,并给出一份对比总结。”
|
||||
- “比较这三个产品页面,告诉我它们的引导流程有什么不同。”
|
||||
|
||||
## 为什么会有该 skill
|
||||
|
||||
该 skill 的核心想法来自更新后的 Chrome DevTools MCP 工作流,详见[让你的编码智能体使用 Chrome DevTools MCP 调试你的浏览器会话](https://developer.chrome.com/blog/chrome-devtools-mcp-debug-your-browser-session):
|
||||
|
||||
- 编码智能体可以复用你正在使用的浏览器会话,而不是强迫你再登录一次
|
||||
- 编码智能体可以接管一个已经激活的调试上下文,例如 Network 中选中的请求或 Elements 中选中的元素
|
||||
- 手动调试和 AI 辅助调试如今可以彼此衔接,而不必分处两个浏览器会话
|
||||
|
||||
这改变了浏览器 skill 的工作重点。
|
||||
|
||||
更宽泛的浏览器工具箱型 skills,往往围绕“传输”来构建:search、fetch、`curl`、CDP,再加上一些站点特定技巧,全都打包在一起。那当然有用,但实时会话调试的重心不同。一旦智能体能附着到你正在使用的浏览器,难点就不再只是“我该怎么到达该页面?”而会变成:
|
||||
|
||||
- 智能体应该在什么时候停留在静态路径上,什么时候接管实时浏览器?
|
||||
- 它该如何从当前页面或已选中的 DevTools 上下文继续,而不是从头重放整个流程?
|
||||
- 它该如何在执行任何变更前,证明浏览器能力真的可用?
|
||||
- 它该如何从过期页面状态、重新渲染、模糊的保存结果和失效的操作目标中恢复?
|
||||
- 它该如何保留可复用的站点知识,同时又不将这些知识变成过时迷信?
|
||||
|
||||
`use-my-browser` 正是为回答这些问题而存在。
|
||||
|
||||
## 能力
|
||||
|
||||
该 skill 可以帮助智能体完成以下事情:
|
||||
该 skill 围绕一个前提来组织:当编码智能体能连接到用户当前的浏览器会话后,哪些情况会真正变得重要。
|
||||
|
||||
| 能力 | 含义 |
|
||||
| -------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- |
|
||||
| 智能工具路由 | 智能体可以根据任务在公共网页搜索、处理后的读取、原始抓取、基于 shell 的抓取和实时浏览器工具之间做出选择,而不是将所有事情都强行塞进同一条路径。 |
|
||||
| 实时 Chrome 控制 | 当登录状态、cookies、当前应用上下文或已选中的 DevTools 目标很重要时,智能体可以接入用户当前的 Chrome 会话。 |
|
||||
| 基于 DevTools 的交互 | 智能体可以在动态页面上使用 DOM 读取、点击、表单填写、上传、控制台检查、网络检查、性能工具以及必要时的截图来进行检查和操作。 |
|
||||
| DevTools 交接 | 如果用户已经在 Elements 中选中了某个元素,或在 Network 中选中了某个请求,智能体就可以直接沿用那个上下文,而不是从头复现问题。 |
|
||||
| 证据优先检查 | 智能体会优先使用快照、DOM 读取、控制台输出、网络请求和直接提取,再考虑截图或重复性的 UI 交互。 |
|
||||
| 媒体提取 | 智能体可以直接从页面提取图片或视频 URL,检查媒体状态,并且只在确实需要像素级证据时才使用渲染后的截图。 |
|
||||
| 并行研究 | 对于彼此独立的目标,智能体可以批量处理公共网页工作,更高效地组织多个站点之间的比较,同时避免对依赖同一可变页面状态的任务并行操作。 |
|
||||
| 隔离浏览器回退 | 当任务需要干净的浏览器上下文,或者实时 Chrome 会话不可用时,智能体可以切换到独立的自动化浏览器,而不是强行通过用户当前的浏览器会话来完成一切。 |
|
||||
| 站点记忆 | 该 skill 支持保存经过验证的站点级备注,例如 URL 模式、平台特征、提取策略和已知陷阱,以便在之后的会话中复用。 |
|
||||
| 安全升级 | 智能体可以从最便宜、最可能成功的路径开始,只在必要时逐步升级,并避免在任务并不真正需要时打扰用户的实时浏览器会话。 |
|
||||
### 目标优先路由
|
||||
|
||||
## 示例用法
|
||||
- 将任务分类为 `static-capable` 或 `browser-required`
|
||||
- 让静态任务走成本最低、但仍足以产出正确证据的路径
|
||||
- 一旦任务真的依赖实时浏览器状态,就阻止它被悄悄降级
|
||||
|
||||
按意图分组时,这些例子最容易理解:
|
||||
### 实时会话中的浏览器操作
|
||||
|
||||
**已登录浏览器操作**
|
||||
- 在用户当前的浏览器会话就是事实来源时复用它
|
||||
- 将渲染后的 UI、可见确认状态、登录状态、懒加载内容以及仅浏览器可见的结构都视为一等证据
|
||||
- 当任务确实发生在浏览器里时,优先使用 MCP 原生浏览器操作,而不是临时拼凑大量脚本
|
||||
|
||||
- `将该视频发到 bilibili 上,最后一次点击留给我`
|
||||
- `检查该已登录的仪表盘,不要让我再登录一次`
|
||||
### 渲染结果检查与 UX 评审
|
||||
|
||||
**网站检查与 UX 审查**
|
||||
- 支持审查页面实际可见的内容,而不是只看静态 HTML 或提取出来的文本所暗示的内容
|
||||
- 适用于 UX 检查、首屏评审、布局确认,以及其他“渲染结果本身就是证据”的任务
|
||||
- 只有在可见体验比静态提取更重要时,才升级到浏览器路径
|
||||
|
||||
- `访问页面 https://xi-xu.me,看看它的 UX 设计怎么样`
|
||||
- `比较这些公开来源,给出引用,并且只有在静态路径失败时才使用浏览器`
|
||||
### DevTools 接力
|
||||
|
||||
**社交网站与动态站点研究**
|
||||
- 当用户已经打开相关页面、元素或请求时,直接从当前调试上下文起步
|
||||
- 支持从已选中的 Elements 和 Network 请求继续
|
||||
- 避免在浏览器已经包含关键线索时,还去重放整套复现流程
|
||||
|
||||
- `去抖音搜索 Xi Xu 的账号,看看他最近发了什么`
|
||||
- `从该懒加载页面里提取真实的图片或视频源地址`
|
||||
### 控制面安全性
|
||||
|
||||
**DevTools 交接**
|
||||
- 为保存、发布、上传和设置类流程加入更严格的确认纪律
|
||||
- 将只读检查与会改动状态的操作分开
|
||||
- 在宣称状态变更成功之前,要求同时具备可见证据和结构性证据
|
||||
- 如果用户希望将最后一次点击或发布动作保留为手动操作,也支持在最终高风险变更前停下
|
||||
|
||||
- `我已经在 DevTools 里选中了失败的请求。解释一下它为什么返回 403`
|
||||
- `我已经在 Elements 里点中了坏掉的元素。找出布局为什么不对`
|
||||
### 深层 DOM 与媒体检查
|
||||
|
||||
**并行比较工作**
|
||||
- 处理 Shadow DOM、iframe、折叠内容、懒加载内容以及仅在渲染后可见的证据
|
||||
- 只有在快照不足时,才使用 DOM 级检查
|
||||
- 区分“提取真实媒体源地址”和“检查渲染后的媒体状态”
|
||||
|
||||
- `同时研究这 5 个项目的网站,并给我一份对比总结`
|
||||
- `比较这三个产品页面,告诉我它们的引导流程有什么不同`
|
||||
### 从选择器到 MCP 的桥接
|
||||
|
||||
- 将已知选择器桥接成 MCP 原生 `uid` 目标
|
||||
- 即使 a11y 树没有直接暴露目标,也能帮助保留真实的浏览器交互
|
||||
- 改进上传和操作目标定位,而不必重建自定义执行器
|
||||
|
||||
### 恢复与歧义处理
|
||||
|
||||
- 面对失效的 `uid`、意外导航、模糊结果和交互失败时,使用一套明确的恢复循环
|
||||
- 只有在这些证据确实能改变下一步行动时,才升级到控制台或网络检查
|
||||
- 当能力状态或页面归属变得不明确时,能够干净地停下
|
||||
|
||||
### 可复用的站点知识
|
||||
|
||||
- 将经过验证的站点特定操作事实存储在 `references/site-patterns/` 下
|
||||
- 将站点知识视为操作证据,而不是道听途说
|
||||
- 当某条站点模式不再有效时,明确支持降级或删除旧结论
|
||||
|
||||
### 并行浏览器归属
|
||||
|
||||
- 支持多页面、多智能体的并行工作,同时避免页面冲突
|
||||
- 定义“一页一主”的归属纪律
|
||||
- 让清理和页面归属变成显式行为,而不是隐含假设
|
||||
|
||||
## 安装
|
||||
|
||||
使用 `skills` CLI 安装该 skill:
|
||||
使用 [`skills` CLI](https://github.com/vercel-labs/skills) 安装该 skill:
|
||||
|
||||
```bash
|
||||
bunx skills add xixu-me/skills -s use-my-browser
|
||||
```
|
||||
|
||||
如果没有 Bun,可以使用 `npx`:
|
||||
如果没有 Bun,可以使用 npm:
|
||||
|
||||
```bash
|
||||
npx skills add xixu-me/skills -s use-my-browser
|
||||
@@ -73,138 +155,119 @@ npx skills add xixu-me/skills -s use-my-browser
|
||||
|
||||
## 前置条件
|
||||
|
||||
当智能体可以通过 Chrome DevTools MCP 复用你当前的 Chrome 会话时,该 skill 的效果最好。若要进行实时浏览器自动化,请先设置 Chrome 远程调试,然后配置 MCP 服务器,使其能自动连接到正在运行的浏览器。
|
||||
|
||||
> [!IMPORTANT]
|
||||
> 开始前请先确保 Chrome 已经在运行。否则智能体可能无法连接到当前的浏览器会话,并可能回退到一个独立的隔离浏览器会话。
|
||||
> 在开始前,请确保 Chrome 已经在运行。否则,智能体可能无法附着到你当前的浏览器会话,而会退回到一个独立的隔离浏览器会话。
|
||||
|
||||
在 Chrome (>=144) 中,访问 `chrome://inspect/#remote-debugging` 以启用远程调试。
|
||||
关于 [Chrome DevTools MCP README](https://github.com/ChromeDevTools/chrome-devtools-mcp?tab=readme-ov-file#automatically-connecting-to-a-running-chrome-instance) 中描述的自动实时会话流程:
|
||||
|
||||

|
||||
1. 在 Chrome(`>=144`)中,打开 `chrome://inspect/#remote-debugging` 并启用 remote debugging。
|
||||
2. 保持 Chrome 处于运行状态。
|
||||
3. 使用 `--autoConnect` 配置 Chrome DevTools MCP。
|
||||
|
||||
要让 Chrome DevTools MCP 服务器连接到正在运行的 Chrome 实例,请在 MCP 服务器配置中使用 `--autoConnect` 命令行参数。
|
||||

|
||||
|
||||
你可以使用 Bun 或 npm 来运行它:
|
||||
下面的默认示例使用 Bun。如果你更偏好 npm,后面也给出了对应的 `npx` 版本。
|
||||
|
||||
```bash
|
||||
bunx chrome-devtools-mcp@latest --autoConnect --no-usage-statistics
|
||||
bunx chrome-devtools-mcp@latest --autoConnect
|
||||
```
|
||||
|
||||
```bash
|
||||
npx chrome-devtools-mcp@latest --autoConnect --no-usage-statistics
|
||||
npx chrome-devtools-mcp@latest --autoConnect
|
||||
```
|
||||
|
||||
许多智能体运行时会使用如下所示的 JSON 风格 MCP 配置:
|
||||
如果你想退出 Chrome DevTools MCP 使用统计,可以在任一命令或下面的配置示例中加上 `--no-usage-statistics`。
|
||||
|
||||
如果 MCP 服务器运行在沙箱中,或者运行在与浏览器不同的机器上,请使用像 `--browserUrl=http://127.0.0.1:9222` 这样的手动连接方式,而不是 `--autoConnect`。这种手动方式要求 Chrome 以 remote debugging port 启动;平台相关的启动命令请参阅 [Chrome DevTools MCP README](https://github.com/ChromeDevTools/chrome-devtools-mcp?tab=readme-ov-file#manual-connection-using-port-forwarding)。
|
||||
|
||||
很多智能体运行时会使用如下 JSON 风格的 MCP 配置:
|
||||
|
||||
```json
|
||||
{
|
||||
"mcpServers": {
|
||||
"chrome-devtools": {
|
||||
"command": "bunx",
|
||||
"args": [
|
||||
"chrome-devtools-mcp@latest",
|
||||
"--autoConnect",
|
||||
"--no-usage-statistics"
|
||||
]
|
||||
"args": ["chrome-devtools-mcp@latest", "--autoConnect"]
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
对于 Codex,MCP 配置可以是这样:
|
||||
对于 Codex,MCP 配置可以像这样:
|
||||
|
||||
```toml
|
||||
[mcp_servers.chrome-devtools]
|
||||
command = "bunx"
|
||||
args = ["chrome-devtools-mcp@latest", "--autoConnect", "--no-usage-statistics"]
|
||||
args = ["chrome-devtools-mcp@latest", "--autoConnect"]
|
||||
```
|
||||
|
||||
## 策略模型
|
||||
> [!TIP]
|
||||
> 在 Chrome DevTools MCP 调试会话进行期间,Chrome 先请求权限、然后在会话激活时显示“Chrome 当前正由自动化测试软件控制”横幅,都是正常现象。
|
||||
|
||||
该 skill 不只是一些浏览器技巧的集合。它教授的是一种浏览策略。
|
||||
## 策略层
|
||||
|
||||
### 1. 在选工具前先定义成功
|
||||
这套策略刻意保持简单:
|
||||
|
||||
智能体从目标开始,而不是从工具开始。它会先判断任务是更偏重引用、交互、调试,还是依赖用户当前的浏览器状态。
|
||||
1. 判断任务属于 `static-capable` 还是 `browser-required`。
|
||||
2. 使用成本最低、但仍能产出用户真正需要之证据的路径。
|
||||
3. 如果任务属于 `browser-required`,就坚持走浏览器路径,而不是悄悄降级。
|
||||
4. 如果用户已经有一个实时调试上下文,就先从那个上下文继续,而不是尝试全新复现。
|
||||
5. 在结束前,判断这次执行是否产生了可复用的站点知识,或者推翻了某个旧假设。
|
||||
|
||||
### 2. 从能够成功的最低成本层开始
|
||||
这也是它与更宽泛的网络 skills 之间最主要的区别。
|
||||
|
||||
默认的路由模型是:
|
||||
在实践中,这意味着:
|
||||
|
||||
1. 公共网页搜索与页面读取
|
||||
2. 处理后的内容读取
|
||||
3. 用于获取源 HTML、请求头或直接资源的原始抓取
|
||||
4. 实时 Chrome DevTools 会话
|
||||
5. 干净的浏览器自动化
|
||||
- `localhost`、本地控制台、上传、拖拽流程,以及保存/发布确认,通常属于 `browser-required`
|
||||
- 带有稳定 URL 且提取目标很小的公开页面,通常应保持在静态路径上
|
||||
- 如果用户希望保留最后一步为手动动作,高风险控制面工作可以在最终变更前停下
|
||||
|
||||
这是一个升级模型,而不是死板的阶梯。如果任务显然依赖当前已登录的浏览器状态,智能体就应该直接从实时会话开始。
|
||||
## 它是如何工作的
|
||||
|
||||
### 3. 将每个结果都当作证据
|
||||
该 skill 由一个入口文件和一组聚焦的参考文档组成:
|
||||
|
||||
每一步都应该更新计划。搜索结果、快照、请求、控制台日志和截图都是证据,而不是形式。该 skill 鼓励智能体停止重复失败策略,并在当前层级已不再提供信息时切换到其他层级。
|
||||
- [`SKILL.md`](./SKILL.md):入口、范围、任务分类、硬性规则,以及参考文件加载指南
|
||||
- [`references/task-routing.md`](./references/task-routing.md):静态检索与实时浏览器路由
|
||||
- [`references/browser-playbook.md`](./references/browser-playbook.md):默认的实时浏览器操作循环
|
||||
- [`references/browser-capability-matrix.md`](./references/browser-capability-matrix.md):通过真实浏览器工具调用来证明浏览器能力
|
||||
- [`references/debug-handoff.md`](./references/debug-handoff.md):从用户当前激活的 DevTools 上下文继续
|
||||
- [`references/control-plane-workflows.md`](./references/control-plane-workflows.md):更安全的保存、发布、上传和更新流程
|
||||
- [`references/anti-automation-friction.md`](./references/anti-automation-friction.md):软 404、认证墙、看似成功但实际上无效的交互,以及反自动化阻力
|
||||
- [`references/deep-dom.md`](./references/deep-dom.md):iframe、Shadow DOM、折叠内容与懒加载证据
|
||||
- [`references/media-inspection.md`](./references/media-inspection.md):真实媒体源地址提取与渲染后媒体检查
|
||||
- [`references/parallel-browser-ownership.md`](./references/parallel-browser-ownership.md):多页面与多智能体的浏览器归属
|
||||
- [`references/selector-bridge.md`](./references/selector-bridge.md):将选择器知识转换成 MCP 原生操作目标
|
||||
- [`references/browser-recovery.md`](./references/browser-recovery.md):从失效目标、重新渲染和模糊 UI 状态中恢复
|
||||
- [站点模式维护规则](./references/site-patterns/README.md):维护域名特定操作知识的规则
|
||||
|
||||
### 4. 保护用户的浏览器会话
|
||||
这些参考文档有意只保持一层深度。入口文件负责决定下一步该加载哪一份文档,这样整个协议才能保持可理解、可组合。
|
||||
|
||||
在使用实时浏览器时:
|
||||
## 实现细节
|
||||
|
||||
- 只有当当前页面状态确实是任务重点时才复用当前页面
|
||||
- 否则,打开或使用一个专门的工作标签页
|
||||
- 避免关闭、重新加载或劫持用户可能仍然关心的标签页
|
||||
- 优先进行结构化提取,而不是侵入式交互
|
||||
该 skill 并没有实现自定义浏览器代理。它记录的是一种面向支持 MCP 的智能体的浏览器会话操作模型。
|
||||
|
||||
### 5. 优先使用一手来源,而不是二手总结
|
||||
关键实现选择包括:
|
||||
|
||||
搜索用于发现。验证则应来自一手来源、官方文档、直接页面、原始响应,以及在需要时取得的实时浏览器会话证据。
|
||||
- **能力优先,而不是工具优先。** 该 skill 通过真实的浏览器工具调用来证明实时浏览器能力,而不是靠 shell 猜测或默认某种集成细节。
|
||||
- **优先复用会话,而不是重新自动化。** 该 skill 假设用户当前的浏览器会话往往是最有价值的工件,尤其是在已登录页面和 DevTools 调查中。
|
||||
- **偏向 MCP 原生操作。** 默认操作循环优先使用快照和 MCP 原生动作,然后才会考虑大范围 DOM 脚本。
|
||||
- **聚焦式升级。** `evaluate_script`、控制台检查和网络检查都属于升级工具,而不是默认操作模式。
|
||||
- **归属纪律。** 任务创建的页面会被保守地跟踪和清理;属于用户的页面则不会被碰。
|
||||
- **经验回路。** 站点特定知识只有在经过验证且可复用时才会被存储;一旦失效,也可以被降级。
|
||||
|
||||
## 该 skill 如何实现这些
|
||||
这让它在一个重要方面比自定义浏览器自动化栈 skill 更现代:它是为 Chrome DevTools MCP 正在推动的“实时会话调试”模式而构建的,而不仅仅是为了远程控制某个浏览器标签页。
|
||||
|
||||
该 skill 被拆分为一个主策略文件和一小组聚焦的参考文件:
|
||||
## 与 `web-access` 的关系
|
||||
|
||||
- [`SKILL.md`](./SKILL.md):主决策模型、安全规则、升级逻辑和示例
|
||||
- [`references/tool-matrix.md`](./references/tool-matrix.md):在公共网页、原始抓取、实时浏览器工具和干净浏览器上下文之间进行选择的路由规则
|
||||
- [`references/session-playbook.md`](./references/session-playbook.md):会话卫生、登录处理、DOM 优先提取和实时会话回退模式
|
||||
- [`references/browser-recipes.md`](./references/browser-recipes.md):具体的浏览器操作和工具映射
|
||||
- [`references/site-patterns/README.md`](./references/site-patterns/README.md):如何保存经过验证的站点特定备注,而不将猜测变成策略
|
||||
该 skill 公开地受到了 `web-access` 的启发,尤其是它对“按证据路由”、保留站点知识,以及将浏览器工作视为一种严肃操作模式而不是最后手段的强调。
|
||||
|
||||
这些文件共同构成了该 skill 的“调度策略”层:
|
||||
区别在于范围。`web-access` 是更广义的 Web 工具箱;`use-my-browser` 则收窄了使命,专注于如何在 MCP 原生工作流中正确接管用户当前的实时浏览器会话。
|
||||
|
||||
- 先尝试什么
|
||||
- 何时升级
|
||||
- 何时切换模式
|
||||
- 如何让彼此独立的研究任务保持分离
|
||||
- 如何避免不必要的浏览器侵入
|
||||
这意味着:
|
||||
|
||||
## 何时使用
|
||||
- 更少“所有 Web 任务都丢到这里”
|
||||
- 更多“这就是如何安全、高效地在用户当前浏览器里操作”
|
||||
- 更少强调自定义浏览器传输层
|
||||
- 更多强调路由、调试接力、确认纪律、恢复机制和页面归属
|
||||
|
||||
在以下情况下使用该 skill:
|
||||
|
||||
- 用户想做网页研究、页面检查或浏览器交互,并且工具选择很重要
|
||||
- 任务依赖当前浏览器会话、cookies 或登录状态
|
||||
- 用户已经打开了相关页面、DevTools 元素或网络请求
|
||||
- 目标站点是动态站点,或者强依赖反爬机制,导致静态抓取不可靠
|
||||
- 任务需要 DOM、控制台、网络、性能或渲染状态等证据
|
||||
- 你需要一种有意识的方法来比较多个网站或公开来源
|
||||
|
||||
## 何时不要使用
|
||||
|
||||
在以下情况下不要使用该 skill:
|
||||
|
||||
- 任务完全是本地的,与网页无关
|
||||
- 普通的公共网页读取已经足够,不需要做浏览器层面的决策
|
||||
- 用户明确表示不希望触碰他们的实时浏览器会话
|
||||
- 工作完全属于隔离自动化,并且不会从实时会话路由模型中受益
|
||||
|
||||
## 它的不同之处
|
||||
|
||||
大多数面向浏览器的 skill 关注的是如何驱动浏览器,而该 skill 关注的是何时、为什么,以及应该在哪一层去做这件事。
|
||||
|
||||
这让它更适合那些需要判断力而不只是点击能力的智能体。
|
||||
|
||||
## 参考资料
|
||||
|
||||
- [Chrome DevTools MCP](https://github.com/ChromeDevTools/chrome-devtools-mcp)
|
||||
- [Let your Coding Agent debug your browser session with Chrome DevTools MCP](https://developer.chrome.com/blog/chrome-devtools-mcp-debug-your-browser-session)
|
||||
|
||||
## 灵感
|
||||
|
||||
- [Web Access](https://github.com/eze-is/web-access)
|
||||
请将该 skill 理解为面向实时会话调试范式的一次专门化策略层重构,而不是 `web-access` 的替代品。
|
||||
+80
-185
@@ -1,215 +1,110 @@
|
||||
---
|
||||
name: use-my-browser
|
||||
description: Use when the user wants browser automation, page inspection, or web research and you need to choose between public-web tools, the live browser session, or a separate browser context, especially for signed-in, dynamic, social, or DevTools-driven pages.
|
||||
compatibility: Environment with chrome-devtools, web, playwright, shell_command, and multi_tool_use.parallel available.
|
||||
description: Use when work depends on the user's live browser session or visible rendered state rather than static fetches, especially for browser debugging contexts or DevTools-selected elements or requests, logged-in dashboards or CMS flows, localhost apps, forms, uploads, downloads, media inspection, DOM or iframe inspection, Shadow DOM, or browser failures that look like soft 404s, auth walls, anti-bot checks, or rate limits.
|
||||
---
|
||||
|
||||
This is the main browser automation strategy skill for nontrivial web work. It teaches the agent when to stay on public-web tools, when to use the live browser session, and when to fall back to a separate browser or raw-fetch path.
|
||||
Do not treat this skill as a generic browsing default. Route from the evidence you need, not from tool preference.
|
||||
|
||||
Despite the name, it covers more than "use my current browser." It also teaches a broader browsing philosophy: define the goal first, choose the right network layer, treat results as evidence, prefer primary sources over recycled summaries, and keep live-session work minimally intrusive.
|
||||
Every task must be classified before you choose a route:
|
||||
|
||||
## When to Use
|
||||
- `static-capable`: the evidence can be produced without live browser state, visible confirmation, or page interaction
|
||||
- `browser-required`: the evidence depends on rendered state, interaction, live session behavior, or browser-only structures
|
||||
|
||||
Use this skill when any of these are true:
|
||||
Only `static-capable` tasks may fall back to static retrieval, `curl`, or other non-browser paths. Once a task is `browser-required`, stay on the browser path and mark missing capability as `blocked` instead of silently downgrading.
|
||||
|
||||
- The user wants public-web research, source verification, or page inspection and the choice of tool matters.
|
||||
- The task depends on the user's current sign-in state or cookies.
|
||||
- The user already has the relevant page, element, or failing request open in Chrome DevTools.
|
||||
- The target is a social platform, anti-bot-heavy site, or other dynamic page where static fetches are likely to miss the real content.
|
||||
- The target page is dynamic, authenticated, or difficult to inspect with search and raw fetch alone.
|
||||
- The task needs the current DOM, console, network activity, performance data, file upload, or rendered media from the live browser session.
|
||||
- The user wants the agent to take over a debugging flow they already started manually in Chrome.
|
||||
## Prerequisite check
|
||||
|
||||
Do not use this skill when:
|
||||
This skill is for work inside the user's live browser session, not for launching a separate fresh automation browser.
|
||||
|
||||
- The task is purely local and does not involve the web at all.
|
||||
- A separate clean browser context is safer than touching the live browsing session.
|
||||
- The user explicitly asks not to use their live browser session.
|
||||
Before doing browser automation, confirm that your environment already has access to a live browser stack that can provide the capabilities the task depends on, such as page inventory, task-owned page creation, page selection, snapshots or visible-state reads, DOM inspection, text or form input, uploads, dialogs, console inspection, and network inspection. The exact stack does not matter here: confirm capability, not brand.
|
||||
|
||||
## Preflight
|
||||
If the live browser stack is unavailable, do not attempt browser automation through this skill. Only `static-capable` work may fall back to static retrieval.
|
||||
|
||||
Before choosing a browsing layer:
|
||||
Live browser automation can trigger anti-bot or anti-automation defenses on some sites. Use browser interaction only when the task truly needs it, and avoid unnecessary repetitive actions once the needed evidence has been obtained.
|
||||
|
||||
- If the task is public and citation-heavy, start with `web`.
|
||||
- If the task needs the live browser session, confirm the Chrome DevTools connection is usable before depending on it.
|
||||
- If a domain note exists under `references/site-patterns/`, read it before browsing that site.
|
||||
- Use [`references/session-playbook.md`](./references/session-playbook.md) for live-browser-session fallback and recovery rules.
|
||||
## Experience loop
|
||||
|
||||
## First Principles
|
||||
Treat site patterns as part of the browser protocol, not as optional background reading.
|
||||
|
||||
### 1. Define success before choosing tools
|
||||
For `browser-required` work, run this loop:
|
||||
|
||||
Start with the outcome, not the tool. Clarify what would count as done:
|
||||
1. As soon as the target domain is known, check whether a matching note already exists under [`references/site-patterns/`](./references/site-patterns/).
|
||||
2. If a note exists, read it before the first meaningful browser mutation on that domain.
|
||||
3. During the run, watch for verified site-specific facts that would change how a future run should operate.
|
||||
4. Before you consider the task complete, decide whether the run produced a reusable fact, disproved an existing fact, or produced no reusable site-specific learning.
|
||||
5. If the run verified something reusable or disproved an existing claim, update the matching note before finishing.
|
||||
|
||||
- What information or action does the user actually need?
|
||||
- Does the task require the user's current browser state?
|
||||
- Is the answer expected to be citation-heavy, interaction-heavy, or debugging-heavy?
|
||||
Do not create a domain note for one-off noise. Do not skip the end-of-run review just because the task itself succeeded.
|
||||
|
||||
### 2. Start with the cheapest layer that can plausibly succeed
|
||||
Writeback is expected when a run verifies any of the following:
|
||||
|
||||
Use the lowest-cost layer that can still reach the goal:
|
||||
- a stable route shape or required query parameter
|
||||
- a login, session inheritance, or `isolatedContext` quirk
|
||||
- a reliable interaction primitive such as hover, keyboard entry, upload sequencing, or a selector bridge pattern
|
||||
- a domain where DOM-generated links are reliable but hand-built URLs are not
|
||||
- predictable anti-automation friction or a misleading platform error state
|
||||
- a reusable media extraction or iframe / Shadow DOM access pattern
|
||||
|
||||
- public-web tools for discovery, citations, and normal page reads
|
||||
- processed or raw reads when you need cheaper content extraction or source-level response data
|
||||
- browser tools when the task depends on live state, interaction, or rendered evidence
|
||||
## Decision guide
|
||||
|
||||
Use [`references/tool-matrix.md`](./references/tool-matrix.md) for the detailed routing rules.
|
||||
Start with the outcome, not the tool. Make the user's goal explicit, define what counts as done, and choose the cheapest route that can still produce the right evidence.
|
||||
|
||||
### 3. Treat every result as evidence
|
||||
Use this routing order:
|
||||
|
||||
Do not repeat the same failed tactic blindly. Each step should update the plan:
|
||||
1. Decide whether the task is `static-capable` or `browser-required`.
|
||||
2. If the task is `static-capable`, load [`references/task-routing.md`](./references/task-routing.md) and stay on the cheapest route that still satisfies the evidence target.
|
||||
3. If the task is `browser-required`, load [`references/browser-playbook.md`](./references/browser-playbook.md).
|
||||
4. If browser-required capability is uncertain in a fresh host session, also load [`references/browser-capability-matrix.md`](./references/browser-capability-matrix.md).
|
||||
5. If the user already has an active browser debugging context, such as a selected inspector element or network request, also load [`references/debug-handoff.md`](./references/debug-handoff.md).
|
||||
6. If the browser-required task touches a logged-in dashboard, admin surface, CMS, editor, or any save / publish / update flow, also load [`references/control-plane-workflows.md`](./references/control-plane-workflows.md).
|
||||
7. If the current failure shape suggests a soft 404, content-unavailable state, suspicious no-op interaction, auth wall, rate limit, or anti-automation defense, also load [`references/anti-automation-friction.md`](./references/anti-automation-friction.md).
|
||||
8. If the browser-required task includes iframe, Shadow DOM, collapsed content, or lazy-loaded evidence, also load [`references/deep-dom.md`](./references/deep-dom.md).
|
||||
9. If the important evidence lives in an image, audio clip, or video, also load [`references/media-inspection.md`](./references/media-inspection.md).
|
||||
10. If browser work can be divided across independent page owners or sub-agents, also load [`references/parallel-browser-ownership.md`](./references/parallel-browser-ownership.md).
|
||||
11. If you already know a reliable selector but need an MCP-native `uid` target, also load [`references/selector-bridge.md`](./references/selector-bridge.md).
|
||||
12. If page actions leave state ambiguous, a page unexpectedly navigates, an old `uid` may have gone stale, or console / network inspection is now needed to explain the next browser decision, also load [`references/browser-recovery.md`](./references/browser-recovery.md).
|
||||
13. If the target site already has a matching domain note under [`references/site-patterns/`](./references/site-patterns/), read that note before operating on the site.
|
||||
|
||||
- Search results may show the target is public, missing, or hidden behind login.
|
||||
- A snapshot may reveal the data is already in the DOM and does not need OCR.
|
||||
- A missing DOM node may mean the site is lazy-loaded, virtualized, gated by interaction, or simply on the wrong page.
|
||||
- A platform saying "not found" may reflect an access path problem rather than a true absence.
|
||||
Treat the following as `browser-required` by default:
|
||||
|
||||
### 4. Preserve the user's session
|
||||
- `localhost`, `127.0.0.1`, or benchmark-style local fixtures
|
||||
- uploads, downloads, drag-and-drop, hover, keyboard-native entry, or visible confirmation states
|
||||
- same-origin iframe inspection, Shadow DOM inspection, `details` / collapsed evidence, or lazy-loaded content
|
||||
- any task where "what the page visibly shows" is itself the evidence
|
||||
|
||||
The live browser session is valuable. Use it carefully:
|
||||
The normal happy path for a common task is this entrypoint plus one or two references, not the entire reference set.
|
||||
|
||||
- Prefer the already connected Chrome DevTools session when the task depends on current state.
|
||||
- Avoid closing or hijacking tabs you did not open.
|
||||
- Prefer your own tab for exploration unless the point of the task is the already selected page, element, or request.
|
||||
- Leave the session cleaner than you found it.
|
||||
## Hard rules
|
||||
|
||||
### 5. Search helps you find sources, not prove claims
|
||||
- Use browser interaction only when live browser state is part of the evidence or required action.
|
||||
- Once a task is `browser-required`, do not silently downgrade.
|
||||
- Treat this file as the entrypoint and each reference file as a single-purpose authority. Do not duplicate rules across files.
|
||||
- Keep reference loading one level deep. Decide the next file from this entrypoint instead of turning one reference into a hub that links to more references.
|
||||
- Do not ask the user to log in just because a page looks restricted. First confirm whether the target content or action is actually blocked.
|
||||
- Prefer site-generated DOM links over hand-built URLs once the page has shown you the path it expects.
|
||||
- Prefer MCP-native actions over script-driven interaction when the task is genuinely an in-browser action.
|
||||
- Only close pages you created.
|
||||
- Prefer primary sources over aggregators or repeated secondary reporting.
|
||||
- If a matching site pattern note exists, read it before the first meaningful browser mutation on that domain.
|
||||
- Do not finish a `browser-required` task without explicitly checking whether the run should create, update, downgrade, or remove a site-pattern claim.
|
||||
- If an existing site-pattern claim fails under comparable conditions, stop trusting it, fall back to the generic workflow, and update the note instead of retrying the stale assumption.
|
||||
- Do not use `curl`, `Invoke-WebRequest`, or shell HTTP fetches for `browser-required` tasks.
|
||||
- Do not treat a generic page-opening tool as evidence that localhost deep interaction is available.
|
||||
- Do not switch routes just because a browser capability probe failed. Record the missing capability and stop.
|
||||
- When the user indicates an active browser debugging context, prefer handoff from that current context over fresh reproduction from scratch.
|
||||
|
||||
Search engines and aggregators are discovery tools. When the task is about truth or verification:
|
||||
## Reference index
|
||||
|
||||
- Use search to locate the likely source
|
||||
- Read the source directly before making a strong claim
|
||||
- Prefer official docs, official pages, raw announcements, and original content over repeated summaries
|
||||
|
||||
### 6. Prefer site-native URLs and complete parameters
|
||||
|
||||
If a site already exposes a link in the DOM, prefer that full URL over a hand-constructed guess. Query parameters, tokens, and generated paths often carry real session or routing context.
|
||||
|
||||
## Session Boundaries and Safety
|
||||
|
||||
The official Chrome DevTools MCP docs matter here:
|
||||
|
||||
- Live-session access can expose all open windows in the selected Chrome profile.
|
||||
- `--autoConnect` is the safe modern pattern for sharing a real Chrome session with an MCP client.
|
||||
- `--browser-url` is a fallback for explicit remote-debug-port setups, but it should not be recommended against the user's normal browsing profile.
|
||||
- A manual remote debugging port on a default profile is riskier than the normal live browser session flow because any local app can connect while the port is open.
|
||||
|
||||
Treat these as background rules:
|
||||
|
||||
- Prefer the current DevTools connection if it already exists.
|
||||
- Mention `--autoConnect` and `--browser-url` only as configuration context or troubleshooting guidance.
|
||||
- Do not steer the user toward remote-debug-port workflows unless the current environment genuinely needs that fallback.
|
||||
|
||||
## Core Workflow
|
||||
|
||||
### Goal-first browsing loop
|
||||
|
||||
1. Define the success condition.
|
||||
2. Choose the cheapest promising layer.
|
||||
3. Inspect the result for evidence.
|
||||
4. Escalate only when the current layer cannot reach the goal.
|
||||
5. Stop when the goal is met, not when every possible path has been explored.
|
||||
|
||||
### Default live browser session workflow
|
||||
|
||||
When a task depends on the user's current browser session:
|
||||
|
||||
1. Inspect available pages with `list_pages`.
|
||||
2. Reuse the selected page if the user's active context is the task.
|
||||
3. Otherwise open or select a dedicated page before exploring.
|
||||
4. Use `take_snapshot` before screenshots whenever structured page data might be enough.
|
||||
5. Use `evaluate_script`, network tools, console tools, and performance tools as the primary evidence sources.
|
||||
6. Use screenshots only when the visual state itself matters or the DOM does not expose enough information.
|
||||
|
||||
Read [`references/browser-recipes.md`](./references/browser-recipes.md) for concrete tool mappings and equivalent browser operations.
|
||||
|
||||
## Chrome DevTools Handoff Patterns
|
||||
|
||||
### Continue from a selected element
|
||||
|
||||
If the user already selected something in the Elements panel:
|
||||
|
||||
- `take_snapshot` can surface the current selection context.
|
||||
- `evaluate_script` is usually the next best tool for reading computed values, attributes, state, or nearby DOM.
|
||||
- Use `click`, `fill`, `hover`, and related tools only after confirming the current structure.
|
||||
|
||||
### Continue from a selected network request
|
||||
|
||||
If the user already highlighted a failing request in the Network panel:
|
||||
|
||||
- Call `get_network_request` without a `reqid` first.
|
||||
- Inspect request and response bodies, headers, status, timing, and failure shape before looking for broader patterns.
|
||||
- Use `list_network_requests` only when you need surrounding context or need to compare multiple requests.
|
||||
|
||||
### Continue from an active debugging page
|
||||
|
||||
If the user is already on the problem page:
|
||||
|
||||
- Start from that page instead of opening a parallel isolated copy.
|
||||
- Preserve the state they already set up unless the user asks for a fresh reproduction.
|
||||
- If you need a second tab for safe experimentation, create one yourself and keep the original page intact.
|
||||
|
||||
## Extraction and Interaction Rules
|
||||
|
||||
Read [`references/session-playbook.md`](./references/session-playbook.md) for the detailed patterns. The short version:
|
||||
|
||||
- Prefer DOM and network evidence over OCR.
|
||||
- Prefer `take_snapshot` over `take_screenshot` for interaction planning.
|
||||
- Prefer `evaluate_script` when the data likely exists but is not visible.
|
||||
- Switch between direct extraction and GUI-style interaction based on what the site actually responds to.
|
||||
- Treat screenshots, reconstructed URLs, and "not found" pages as things to verify, not things to trust immediately.
|
||||
|
||||
## Public Web vs Live Session
|
||||
|
||||
This skill should not collapse into "always use the browser."
|
||||
|
||||
- Public-web tasks still belong to this skill when the main question is "which layer should I use first?"
|
||||
- Start with public-web tools for citation-heavy work and escalate only when the cheaper path cannot reach the goal.
|
||||
- Use [`references/tool-matrix.md`](./references/tool-matrix.md) for the routing decision and [`references/browser-recipes.md`](./references/browser-recipes.md) for the concrete operations.
|
||||
|
||||
## Parallel Research Policy
|
||||
|
||||
For multiple independent public research targets:
|
||||
|
||||
- Batch `web.search_query` requests in one call when possible.
|
||||
- Batch `web.open` calls when reading several sources.
|
||||
- Use `multi_tool_use.parallel` for independent shell or local-doc reads, not for browser steps that depend on the same selected page state.
|
||||
- Use [`references/session-playbook.md`](./references/session-playbook.md) for the rules on when agent-level parallelism is worth it and how to frame it safely.
|
||||
|
||||
## Red Flags
|
||||
|
||||
Stop and change approach if you notice any of these:
|
||||
|
||||
- You are about to use the live browser session for a task that only needs public citations.
|
||||
- You are about to close, reload, or navigate a page the user may still be using.
|
||||
- You reached for screenshots before checking whether the DOM or network already contains the answer.
|
||||
- You are ignoring a currently selected DevTools request or element and starting from scratch.
|
||||
- You are hand-constructing site URLs even though the page already exposes the real link with parameters.
|
||||
- You are treating a platform "not found" message as definitive before checking whether the access path itself is wrong.
|
||||
- You are about to recommend remote debugging on the user's normal browsing profile.
|
||||
- You are using Playwright by habit even though the goal depends on the user's current signed-in Chrome state.
|
||||
|
||||
## Examples
|
||||
|
||||
**Use this skill**
|
||||
|
||||
- "I already have the failing request selected in DevTools. Explain why it returns 403."
|
||||
- "Check this dashboard in my logged-in browser without making me sign in again."
|
||||
- "I clicked into the broken component in Elements. Figure out why the layout is wrong."
|
||||
- "Pull the real image or video source from this lazy-loaded page."
|
||||
- "Read this public doc and tell me the structured metadata without opening a browser if a fetch is enough."
|
||||
- "Compare these three public sources, cite them, and only touch the browser if the static path fails."
|
||||
- "Go through this social site and find the real content even if search results and direct fetches are weak."
|
||||
|
||||
**Do not use this skill**
|
||||
|
||||
- "Rename these local files and update the import paths."
|
||||
- "Refactor this parser and run the unit tests."
|
||||
- "Open a clean browser and test the unauthenticated signup flow."
|
||||
|
||||
## Reference Files
|
||||
|
||||
- [`references/tool-matrix.md`](./references/tool-matrix.md): choose between `web`, `chrome-devtools`, `playwright`, and raw-fetch paths.
|
||||
- [`references/session-playbook.md`](./references/session-playbook.md): tab hygiene, DOM/media extraction, login handling, and fallback tactics.
|
||||
- [`references/browser-recipes.md`](./references/browser-recipes.md): concrete browser operations for tab control, extraction, interaction, and audits.
|
||||
- [`references/site-patterns/README.md`](./references/site-patterns/README.md): format for validated domain-specific notes.
|
||||
- [`references/task-routing.md`](./references/task-routing.md): static retrieval vs live browser routing
|
||||
- [`references/browser-playbook.md`](./references/browser-playbook.md): core page-action protocol and base browser loop
|
||||
- [`references/browser-capability-matrix.md`](./references/browser-capability-matrix.md): capability proof for uncertain host sessions
|
||||
- [`references/debug-handoff.md`](./references/debug-handoff.md): active debugging-context handoff
|
||||
- [`references/control-plane-workflows.md`](./references/control-plane-workflows.md): logged-in dashboard / CMS save-publish discipline
|
||||
- [`references/anti-automation-friction.md`](./references/anti-automation-friction.md): soft 404 / auth / anti-automation classification
|
||||
- [`references/deep-dom.md`](./references/deep-dom.md): iframe, Shadow DOM, collapsed, or lazy-loaded evidence
|
||||
- [`references/media-inspection.md`](./references/media-inspection.md): image, audio, and video evidence
|
||||
- [`references/parallel-browser-ownership.md`](./references/parallel-browser-ownership.md): multi-owner browser coordination
|
||||
- [`references/selector-bridge.md`](./references/selector-bridge.md): selector-to-`uid` bridging
|
||||
- [`references/browser-recovery.md`](./references/browser-recovery.md): stale `uid`, navigation drift, and console / network escalation
|
||||
- [`references/site-patterns/README.md`](./references/site-patterns/README.md): site-pattern note maintenance rules
|
||||
- [site-patterns/{domain}.md](./references/site-patterns/): existing domain-specific operating knowledge
|
||||
@@ -0,0 +1,122 @@
|
||||
# Anti-Automation Friction
|
||||
|
||||
Load this reference only after the task is already `browser-required` and the current failure shape suggests a soft 404, content-unavailable state, suspicious no-op interaction, auth wall, rate limit, or anti-automation defense.
|
||||
|
||||
This file is for diagnosis and stop-loss behavior when a browser task begins to look blocked for reasons other than an ordinary product bug.
|
||||
|
||||
## Core rule
|
||||
|
||||
Do not answer uncertainty with faster retries.
|
||||
|
||||
When the page starts behaving like a defensive surface:
|
||||
|
||||
- slow down
|
||||
- collect one fresh round of evidence
|
||||
- classify the failure
|
||||
- try one deliberate alternative only when the classification supports it
|
||||
|
||||
Do not brute-force the same click, navigation, or form action.
|
||||
|
||||
## Three diagnoses
|
||||
|
||||
Classify the failure into one of these buckets before doing anything else:
|
||||
|
||||
### Route or parameter error
|
||||
|
||||
Typical signals:
|
||||
|
||||
- a hand-built URL fails while a DOM-discovered path is still available
|
||||
- the page says `not found` or `unavailable`, but surrounding list pages still show the target
|
||||
- the same content becomes reachable only through a site-generated `href`
|
||||
|
||||
Preferred response:
|
||||
|
||||
- prefer the DOM-discovered route over the hand-built route
|
||||
- preserve site-generated query parameters and route shape
|
||||
- retry once with the site-generated path, not with more guessed URLs
|
||||
|
||||
### Missing auth or session
|
||||
|
||||
Typical signals:
|
||||
|
||||
- redirect to a login route
|
||||
- sign-in wall replaces the target content or control
|
||||
- the page clearly indicates that the current session lacks permission
|
||||
|
||||
Preferred response:
|
||||
|
||||
- confirm that the missing content or action is actually blocked
|
||||
- keep the diagnosis specific to the blocked control or content
|
||||
- ask for login help only when the current session truly cannot continue
|
||||
|
||||
### Anti-automation friction
|
||||
|
||||
Typical signals:
|
||||
|
||||
- repeated no-op clicks on controls that should be actionable
|
||||
- content intermittently flips between available and unavailable without a product-level explanation
|
||||
- rate-limit, bot-check, or defensive copy appears
|
||||
- the same route behaves inconsistently within a short span
|
||||
- the page seems present, but the action path becomes unusually fragile after repeated automation
|
||||
|
||||
Preferred response:
|
||||
|
||||
- reduce mutation frequency
|
||||
- switch to the smallest reliable read-only probe
|
||||
- stop and report once the page is plausibly in a defensive state
|
||||
|
||||
## Compact decision path
|
||||
|
||||
Use this order:
|
||||
|
||||
1. Re-snapshot and confirm current visible state.
|
||||
2. Ask whether the failure is better explained by route shape, auth state, or defensive behavior.
|
||||
3. If route shape is the strongest hypothesis, prefer a DOM-discovered link.
|
||||
4. If auth is the strongest hypothesis, confirm the specific blocked content or control.
|
||||
5. If defensive behavior is the strongest hypothesis, stop escalating mutation pressure.
|
||||
|
||||
Do not pursue all three branches at once.
|
||||
|
||||
## Stop-loss behavior
|
||||
|
||||
When defensive behavior is plausible:
|
||||
|
||||
- do not hammer the same action
|
||||
- do not fan out many fresh tabs
|
||||
- do not keep inventing new hand-built URLs
|
||||
- do not convert a read-only task into a write-heavy task
|
||||
|
||||
Prefer:
|
||||
|
||||
- one current page
|
||||
- one fresh snapshot
|
||||
- one deliberate alternative if warranted
|
||||
- then stop and report
|
||||
|
||||
The goal is to preserve evidence quality while minimizing additional pressure on the site.
|
||||
|
||||
## Read-only bias
|
||||
|
||||
When the target is a social platform, creator surface, production control plane, or other high-risk authenticated site, prefer read-only investigation whenever that still answers the user's question.
|
||||
|
||||
If a write action is required and defensive behavior is already plausible, say so explicitly before retrying.
|
||||
|
||||
## What to report
|
||||
|
||||
When you stop on anti-automation grounds, report:
|
||||
|
||||
- the strongest diagnosis
|
||||
- the key evidence that supports it
|
||||
- the smallest next step that would be safe, if any
|
||||
|
||||
Good examples:
|
||||
|
||||
- the site-generated detail link exists, but the hand-built URL produces a soft 404
|
||||
- the current session is still being redirected to sign-in for the requested control
|
||||
- the control became no-op after repeated attempts and the page now looks rate-limited
|
||||
|
||||
## Boundary
|
||||
|
||||
This file is for failure classification and stop-loss behavior. It does not replace the ordinary browser loop or domain-note discipline.
|
||||
|
||||
Once the failure is classified, return to the skill entrypoint for the next reference instead of expanding this file into a second routing hub.
|
||||
@@ -0,0 +1,48 @@
|
||||
# Browser capability matrix
|
||||
|
||||
Use this reference when the task is already `browser-required` but you still need to prove that the live browser stack is actually usable in the current session.
|
||||
|
||||
This file complements the live-browser playbook. It makes the capability gate executable.
|
||||
|
||||
## Rule
|
||||
|
||||
Do not probe by searching for shell commands, guessed binaries, or text labels. Prove capability through real browser-tool calls.
|
||||
|
||||
## Capability matrix
|
||||
|
||||
| Capability | Example proof in a live-browser host | What counts as failure |
|
||||
| ------------------------ | ----------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------- |
|
||||
| page inventory | `list_pages` returns the current page inventory | no browser tool call exists or the call errors before inventory is returned |
|
||||
| task-owned page creation | `new_page` creates an isolated task page | no browser tool can create a page, or creation is forbidden in the current session |
|
||||
| page selection | `select_page` succeeds on the created page | selection cannot be targeted to the task-owned page |
|
||||
| visible-state read | `take_snapshot` or equivalent visible-state call returns page state | only static fetching is available |
|
||||
| DOM-level script read | `evaluate_script` can read `document.title`, `location.href`, or a scoped DOM target when the task needs DOM-level inspection | the task depends on DOM-level reads but no DOM-evaluation path exists |
|
||||
| upload support | `upload_file` is callable on a known file input for upload tasks | the task depends on upload behavior but uploads require unsupported tool behavior |
|
||||
|
||||
## Minimum proof sequence
|
||||
|
||||
For a fresh browser-required task, prove the smallest set of capabilities that the task actually depends on:
|
||||
|
||||
1. Call `list_pages`.
|
||||
2. Create one task-owned page with `new_page`.
|
||||
3. Select that page.
|
||||
4. Read visible state from a snapshot-style call.
|
||||
5. Add one DOM-level script read only when the task needs DOM inspection, selector bridging, deep extraction, or similar script-level understanding.
|
||||
6. Add one upload proof only when the task really depends on upload behavior.
|
||||
|
||||
If the required steps for the current task succeed, the browser capability gate is satisfied for that run.
|
||||
|
||||
## Localhost rule
|
||||
|
||||
If the task targets `localhost` or `127.0.0.1`:
|
||||
|
||||
- do not treat a generic static opener as equivalent to browser capability
|
||||
- the proof must come from a task-owned browser page that can actually be selected and inspected
|
||||
|
||||
## Failure handling
|
||||
|
||||
If any required step fails:
|
||||
|
||||
- record the missing capability by name
|
||||
- stop the run as `blocked`
|
||||
- do not switch to `curl`, `Invoke-WebRequest`, shell HTTP fetches, or a generic page opener for the same browser-required task
|
||||
@@ -0,0 +1,222 @@
|
||||
# Browser Playbook
|
||||
|
||||
This playbook is the core page-action and base-protocol reference for live browser work. Load it after the skill entrypoint has already classified the task as `browser-required`.
|
||||
|
||||
## Live-browser capability gate
|
||||
|
||||
The capability gate is defined at the skill entrypoint and made executable in the dedicated capability matrix.
|
||||
|
||||
Use that matrix when capability still needs to be proven in the current session. This playbook assumes the task is already on the live-browser path and either:
|
||||
|
||||
- the capability gate has already been satisfied
|
||||
- or the run has already been marked `blocked`
|
||||
|
||||
Operational consequences that still matter here:
|
||||
|
||||
- do not begin browser mutation until the required capability is actually available
|
||||
- if capability is missing, stop the run as `blocked` instead of silently downgrading
|
||||
- for `localhost` and `127.0.0.1`, only continue on a task-owned browser page rather than a generic static opener
|
||||
|
||||
## Default loop
|
||||
|
||||
Use this as the normal operating loop for live browser work:
|
||||
|
||||
1. Call `list_pages` and update your page ledger.
|
||||
2. Create a task-owned page with `new_page` only when you need one.
|
||||
3. Call `select_page(pageId, bringToFront=false)` before page work.
|
||||
4. Call `take_snapshot` to understand the current page state.
|
||||
5. Prefer MCP-native actions first.
|
||||
6. Refresh page understanding after any action that could change the UI.
|
||||
7. Use `evaluate_script` only when snapshot understanding is insufficient or the task is truly DOM-direct.
|
||||
|
||||
The loop is meant to stay lightweight. Do not over-operate once the evidence you need has been obtained.
|
||||
|
||||
Maintain a lightweight page ledger for ordinary browser runs. At minimum, track:
|
||||
|
||||
- the current `pageId`
|
||||
- the best identifying URL or title
|
||||
- whether the page was created by you
|
||||
- whether it should be closed at task exit
|
||||
|
||||
If multi-owner coordination or `isolatedContext` boundaries become important, expand that ledger with the ownership reference instead of overloading this base protocol.
|
||||
|
||||
## Page lifecycle
|
||||
|
||||
### `list_pages`
|
||||
|
||||
Use `list_pages` at the start of browser work and whenever page inventory may have changed. Its job is to support the page ledger, not to become a constant polling habit.
|
||||
|
||||
### `new_page`
|
||||
|
||||
Use `new_page` for fresh task-owned investigation, for task-specific `isolatedContext`, or when you need to inspect a discovered link without disturbing the current flow.
|
||||
|
||||
Do not open a new page for every step. Reuse the current task-owned page when preserving in-page state matters.
|
||||
|
||||
### `select_page`
|
||||
|
||||
Treat `select_page(pageId, bringToFront=false)` as required protocol before every page-level action. Selection is not a convenience; it is how you keep the action tied to the right page.
|
||||
|
||||
### `take_snapshot`
|
||||
|
||||
Use `take_snapshot` as the default way to understand the page.
|
||||
|
||||
Take a fresh snapshot when:
|
||||
|
||||
- a page just opened
|
||||
- a page just navigated
|
||||
- a click or form submission may have changed the UI
|
||||
- you need fresh `uid`s
|
||||
- a previously targeted `uid` may have gone stale
|
||||
|
||||
Use `take_snapshot(verbose=true)` only when a structural question remains unanswered and the extra a11y-tree detail would change the next action.
|
||||
|
||||
### `navigate_page`
|
||||
|
||||
Use `navigate_page` for reload, back or forward history, or direct navigation to a known safe URL. Add `ignoreCache=true` only when stale cached assets or responses are the likely reason the view is wrong.
|
||||
|
||||
Use `handleBeforeUnload` only when navigation itself may trigger a native leave-page dialog. Use `initScript` only when the next navigation truly needs early-document instrumentation.
|
||||
|
||||
When positive evidence shows the target does not exist, stop there. A stop-loss task is complete once the absence has been demonstrated; do not switch routes just to "check one more time."
|
||||
|
||||
## When to use each key MCP tool
|
||||
|
||||
### `evaluate_script`
|
||||
|
||||
Use `evaluate_script` when you need DOM-level depth that the snapshot does not provide, including:
|
||||
|
||||
- extracting hidden or structured data
|
||||
- inspecting dynamically generated URLs
|
||||
- annotating the DOM for selector bridging
|
||||
- cleaning up temporary bridge markers
|
||||
|
||||
`evaluate_script` should deepen page understanding, not replace MCP-native interaction by default.
|
||||
|
||||
Before broad DOM traversal, scope the query to the smallest trustworthy host or business container you can identify. Page-wide scraping is a fallback, not a default.
|
||||
|
||||
If the task is really about iframe traversal, Shadow DOM structure, lazy-loaded evidence, media state, or selector bridge mechanics, switch to the specialized reference.
|
||||
|
||||
### `wait_for`
|
||||
|
||||
Use `wait_for` after actions that should cause visible page changes but need time to settle, such as:
|
||||
|
||||
- search result loads
|
||||
- modal openings
|
||||
- validation messages
|
||||
- upload completion states
|
||||
- SPA route changes
|
||||
|
||||
Prefer waiting for meaningful text over fixed sleeps.
|
||||
|
||||
Prefer text that appears only after the action succeeds. If text is weak, confirm the state change through structured signals from `evaluate_script` such as `location.href`, element counts, `scrollHeight`, upload state, or media timestamps.
|
||||
|
||||
### Interaction-mode tools
|
||||
|
||||
- use `hover` for reveal-on-hover UI such as menus, tooltips, avatar cards, or hover action bars
|
||||
- use `drag` for real drag-and-drop or reorder interactions when both source and target are identifiable
|
||||
- use `press_key` when the semantic action is really a key press, such as focus movement, shortcuts, escape-to-close, or keyboard-driven scrolling
|
||||
- use `type_text` after focus is already correct and the page needs keyboard-native entry, such as rich editors, masked fields, token inputs, or typeahead widgets
|
||||
|
||||
If all you need is to set a stable value in a standard field, `fill` or `fill_form` is usually cheaper and clearer than `type_text`.
|
||||
|
||||
### `emulate` and `resize_page`
|
||||
|
||||
Use `resize_page` when viewport size alone is the question.
|
||||
|
||||
Use `emulate` when the environment itself is part of the evidence, such as:
|
||||
|
||||
- mobile or touch behavior
|
||||
- light or dark mode
|
||||
- throttled network or CPU
|
||||
- user-agent-sensitive rendering
|
||||
|
||||
Do not switch environment "just to be thorough." Change it only when the task depends on that state.
|
||||
|
||||
## Form, upload, dialog, and screenshot rules
|
||||
|
||||
### Forms
|
||||
|
||||
Start with `take_snapshot` to identify the right inputs.
|
||||
|
||||
Use `fill` or `fill_form` when direct value assignment is clean. Use `type_text` when the field reacts to each key or the page enables the next action only after typing events. Use `press_key` alongside either path when the next semantic action is really keyboard-based.
|
||||
|
||||
Refresh the snapshot after form interactions when validation, formatting, or conditional UI may have changed the page.
|
||||
|
||||
Do not force `fill_form` onto highly custom controls. If a page mixes ordinary fields with custom selects, uploads, or tokenized inputs, combine batched filling with targeted native actions instead of trying to make one call do everything.
|
||||
|
||||
Use `evaluate_script` only when the form is highly custom and MCP-native fill cannot target it reliably.
|
||||
|
||||
### Uploads
|
||||
|
||||
Use `take_snapshot` to find the file input or upload trigger.
|
||||
|
||||
Prefer `upload_file(uid)` over script-driven file manipulation.
|
||||
|
||||
If the upload target is not clearly actionable from the snapshot, switch to the selector bridge reference instead of improvising ad hoc upload targeting here.
|
||||
|
||||
After upload, take a fresh snapshot and wait for a meaningful confirmation state when the page does not already make success obvious.
|
||||
|
||||
### Dialogs
|
||||
|
||||
Use `handle_dialog` for native `alert`, `confirm`, or `prompt` dialogs.
|
||||
|
||||
Preferred sequence:
|
||||
|
||||
1. Perform the action expected to trigger the dialog.
|
||||
2. Call `handle_dialog` immediately once it appears.
|
||||
3. Provide `promptText` only when the flow really needs it.
|
||||
4. Refresh page understanding after the dialog resolves.
|
||||
|
||||
Do not try to fight a native dialog with DOM scripting or random clicks.
|
||||
|
||||
### Screenshots
|
||||
|
||||
Use `take_screenshot` when the visual rendering matters more than the accessibility tree, such as charts, canvas, video frames, popup blocking, visual bugs, or layout confirmation.
|
||||
|
||||
Choose the narrowest screenshot that proves the point: element when one control is the evidence, page when layout context matters, and `fullPage=true` only when document-wide vertical context matters.
|
||||
|
||||
Do not use screenshots as the default understanding tool when a snapshot would answer the same question more directly.
|
||||
|
||||
## Post-run experience review
|
||||
|
||||
Before cleanup, return to the skill entrypoint's experience loop and site-pattern hard rules to decide whether the run should create, update, downgrade, or leave unchanged any domain note.
|
||||
|
||||
The playbook-specific consequence is timing: do that review before closing task-owned pages or discarding the current run context, while the evidence is still easy to inspect.
|
||||
|
||||
If the run has entered stale-`uid`, unexpected-navigation, contaminated-extraction, or console / network ambiguity territory, switch to the recovery reference before deciding the run is complete.
|
||||
|
||||
## Cleanup
|
||||
|
||||
Only close pages you created.
|
||||
|
||||
- close pages where `createdByMe=true` and `closeOnExit=true`
|
||||
- leave user-owned pages alone
|
||||
- if the browser host cannot close the last open page, do not force page closure
|
||||
|
||||
Refresh the page ledger after every new page, direct navigation, or page disappearance that could change ownership interpretation.
|
||||
|
||||
If a page drifts in inventory, is renumbered, or loses explicit ownership evidence:
|
||||
|
||||
- record the ambiguity
|
||||
- stop cleanup for that page
|
||||
- do not guess which page to close
|
||||
|
||||
Cleanup that remains incomplete because of ownership ambiguity is a concern to report, not a protocol violation.
|
||||
|
||||
## Host and upstream boundaries
|
||||
|
||||
Some browser-task rough edges belong in the skill, and some belong upstream in the host integration.
|
||||
|
||||
Skill-level workaround territory:
|
||||
|
||||
- choose better wait signals when text anchors are weak
|
||||
- scope DOM traversal before scraping
|
||||
- use selector bridge earlier for file uploads
|
||||
- switch evidence sources explicitly for media tasks
|
||||
|
||||
Host or MCP integration territory:
|
||||
|
||||
- richer support for non-text wait primitives when no visible text exists
|
||||
- more consistent exposure of hidden but actionable upload controls in snapshots
|
||||
- better guardrails against extension-injected DOM noise
|
||||
|
||||
When the workaround is reusable and site-specific, record it in the matching site pattern when you can, but do not pretend the host limitation itself has been fixed by documentation alone.
|
||||
@@ -1,98 +0,0 @@
|
||||
# Browser Recipes
|
||||
|
||||
This file lists the concrete browser operations and their closest tool equivalents.
|
||||
|
||||
## Processed Read and Raw Fetch Layers
|
||||
|
||||
These two layers sit before full browser attachment when the task does not yet need live browser state.
|
||||
|
||||
### Processed read
|
||||
|
||||
Use a processed read when:
|
||||
|
||||
- the URL is already known
|
||||
- the page is mostly article, documentation, or PDF content
|
||||
- you need the page text more than the original response shape
|
||||
|
||||
Preferred options:
|
||||
|
||||
- `web.open` for the standard processed page
|
||||
- an external markdown mirror only when token savings matter and fidelity is still acceptable for the task
|
||||
|
||||
### Raw fetch
|
||||
|
||||
Use a raw fetch when:
|
||||
|
||||
- you need source HTML, headers, JSON-LD, or a direct asset
|
||||
- the distinction between rendered text and original response data matters
|
||||
|
||||
Preferred options:
|
||||
|
||||
- `shell_command` with a native fetch tool such as `Invoke-WebRequest` or `curl.exe`
|
||||
- save large responses to a file when inline output would be noisy
|
||||
|
||||
## Page and Tab Control
|
||||
|
||||
| Goal | Equivalent tool or action |
|
||||
| ------------------------------ | ----------------------------------------- |
|
||||
| List open tabs | `chrome-devtools.list_pages` |
|
||||
| Create a new tab | `chrome-devtools.new_page` |
|
||||
| Switch to an existing tab | `chrome-devtools.select_page` |
|
||||
| Close your own tab | `chrome-devtools.close_page` |
|
||||
| Go to a URL in the current tab | `chrome-devtools.navigate_page` |
|
||||
| Go back | `chrome-devtools.navigate_page` with back |
|
||||
|
||||
## Inspect and Extract
|
||||
|
||||
| Goal | Equivalent tool or action |
|
||||
| --------------------------------------- | ----------------------------------------------------- |
|
||||
| Run arbitrary page script | `chrome-devtools.evaluate_script` |
|
||||
| Read the accessible page structure | `chrome-devtools.take_snapshot` |
|
||||
| Get rendered image state | `chrome-devtools.take_screenshot` |
|
||||
| Inspect the selected request in Network | `chrome-devtools.get_network_request` without `reqid` |
|
||||
| Inspect broader traffic | `chrome-devtools.list_network_requests` |
|
||||
| Inspect console output | `chrome-devtools.list_console_messages` |
|
||||
|
||||
## Interaction
|
||||
|
||||
| Goal | Equivalent tool or action |
|
||||
| --------------------- | ------------------------------------- |
|
||||
| Click an element | `chrome-devtools.click` |
|
||||
| Hover an element | `chrome-devtools.hover` |
|
||||
| Fill an input | `chrome-devtools.fill` or `fill_form` |
|
||||
| Upload files | `chrome-devtools.upload_file` |
|
||||
| Drag and drop | `chrome-devtools.drag` |
|
||||
| Keyboard-only actions | `chrome-devtools.press_key` |
|
||||
|
||||
## Scroll and Wait Patterns
|
||||
|
||||
There is no dedicated `scroll` endpoint in the Chrome DevTools toolset. Use one of these:
|
||||
|
||||
- `evaluate_script(() => window.scrollBy(0, 1200))`
|
||||
- `evaluate_script(() => window.scrollTo(0, document.body.scrollHeight))`
|
||||
- `press_key("PageDown")` when a keyboard-style interaction is more realistic
|
||||
|
||||
After scrolling or a major interaction:
|
||||
|
||||
- use `wait_for` if you know the next text or state to wait on
|
||||
- otherwise re-run `take_snapshot`
|
||||
|
||||
## Performance, Memory, and Audits
|
||||
|
||||
| Goal | Equivalent tool or action |
|
||||
| ----------------------------------------- | --------------------------------------------- |
|
||||
| Start a performance trace | `chrome-devtools.performance_start_trace` |
|
||||
| Stop and save trace | `chrome-devtools.performance_stop_trace` |
|
||||
| Analyze a highlighted performance insight | `chrome-devtools.performance_analyze_insight` |
|
||||
| Capture a memory snapshot | `chrome-devtools.take_memory_snapshot` |
|
||||
| Run a Lighthouse audit | `chrome-devtools.lighthouse_audit` |
|
||||
|
||||
## When to Switch to Playwright
|
||||
|
||||
Switch to Playwright when:
|
||||
|
||||
- The task wants a clean browser context
|
||||
- The live Chrome session is unavailable and cannot be attached
|
||||
- The work is browser automation, not reuse of the current signed-in session
|
||||
|
||||
Playwright is a fallback, not an equivalent replacement for the user's current browser session or state.
|
||||
@@ -0,0 +1,152 @@
|
||||
# Browser Recovery
|
||||
|
||||
Load this reference only after the task is already `browser-required` and the run has entered ambiguity, failed interaction recovery, or console / network escalation.
|
||||
|
||||
This file is for recovering from stale assumptions inside the current browser run. It does not replace the base page-action protocol.
|
||||
|
||||
## Scope
|
||||
|
||||
Use this reference when any of the following is true:
|
||||
|
||||
- a click, fill, or upload did not produce the expected visible state
|
||||
- an old `uid` may have gone stale after rerender or navigation
|
||||
- the page navigated unexpectedly
|
||||
- DOM extraction now looks contaminated or over-broad
|
||||
- a selector bridge stopped working
|
||||
- the page has a native interaction path, but the current action mode looks wrong
|
||||
- console or network inspection is now needed to explain the next browser decision
|
||||
|
||||
## Core recovery rule
|
||||
|
||||
Recover from the current page state before branching into deeper tactics.
|
||||
|
||||
Use this order:
|
||||
|
||||
1. Re-select the intended page.
|
||||
2. Refresh page understanding with a fresh snapshot.
|
||||
3. Decide whether the old `uid`, page assumption, or extracted evidence is now stale.
|
||||
4. Try one deliberate escalation that matches the strongest hypothesis.
|
||||
5. Stop once the next browser decision is clear.
|
||||
|
||||
Do not stack retries, fresh tabs, console dives, and DOM rewrites all at once.
|
||||
|
||||
## Rerender and stale uid
|
||||
|
||||
If a click, fill, or upload fails:
|
||||
|
||||
- re-run `select_page(pageId, bringToFront=false)`
|
||||
- take a fresh snapshot
|
||||
- check whether the old `uid` disappeared after rerender or navigation
|
||||
- reacquire a fresh target before trying the action again
|
||||
|
||||
Do not trust a pre-action `uid` after:
|
||||
|
||||
- route change
|
||||
- modal open or close
|
||||
- form validation that rewrites the region
|
||||
- upload progress that swaps the control tree
|
||||
|
||||
If the page structure is still unclear after a fresh snapshot, use the smallest DOM read that can re-anchor the next action.
|
||||
|
||||
## Unexpected navigation
|
||||
|
||||
If the page navigates unexpectedly:
|
||||
|
||||
- update the page ledger if needed
|
||||
- confirm that you still own the current page
|
||||
- take a fresh snapshot before doing anything else
|
||||
- decide whether the new page is the intended continuation or a drift state
|
||||
|
||||
If the new page positively demonstrates the target does not exist, stop there instead of forcing more navigation.
|
||||
|
||||
## Extraction contamination
|
||||
|
||||
If DOM extraction looks contaminated:
|
||||
|
||||
- stop trusting the broad result
|
||||
- check for stylesheet blobs, extension noise, or unrelated widget text
|
||||
- narrow the query to the real target container or host
|
||||
- prefer host-level rendered text when the task is about what the user actually sees
|
||||
|
||||
Typical contamination cues:
|
||||
|
||||
- a huge stylesheet blob in extracted text
|
||||
- extension-injected ids or element names
|
||||
- unrelated widget text that does not match the current page goal
|
||||
|
||||
## Bridge recovery
|
||||
|
||||
If a selector bridge stops working:
|
||||
|
||||
- rebuild the bridge from the beginning
|
||||
- prefer a fresh temporary `aria-label`
|
||||
- remove stale markers before retrying when possible
|
||||
- fall back to pure `evaluate_script` only when MCP-native interaction is genuinely unavailable
|
||||
|
||||
Do not keep retrying an old bridge target after the page has rerendered.
|
||||
|
||||
## Interaction-mode fallback
|
||||
|
||||
If the page is still awkward even though a native interaction path exists, switch modes deliberately:
|
||||
|
||||
- use `hover` for reveal-on-hover UI
|
||||
- use `press_key` for keyboard-driven widgets or lazy-load scrolling
|
||||
- use `drag` for real drag-and-drop widgets
|
||||
- use `navigate_page` when the real action is back, forward, reload, or direct navigation
|
||||
|
||||
Change only one interaction mode at a time. The goal is to explain which mode matches the UI, not to brute-force every tool.
|
||||
|
||||
## Console and network escalation
|
||||
|
||||
Escalate into console or network inspection only after a user action still leaves the page state ambiguous.
|
||||
|
||||
Check the console first when:
|
||||
|
||||
- the page looks frozen
|
||||
- validation never appears
|
||||
- a widget disappears
|
||||
- a script error is the likely cause
|
||||
|
||||
Check the network first when:
|
||||
|
||||
- a submit, save, search, or load should have produced a request
|
||||
- the visible page state suggests a backend or routing failure
|
||||
|
||||
Use a light escalation pattern:
|
||||
|
||||
1. perform the user action
|
||||
2. refresh page understanding if needed
|
||||
3. inspect the console list or network list based on the stronger hypothesis
|
||||
4. inspect one concrete message or request only if the list still leaves the cause unclear
|
||||
|
||||
Go deeper only when the extra detail could change the next browser decision.
|
||||
|
||||
Stay lightweight when:
|
||||
|
||||
- the page already recovered after a fresh snapshot
|
||||
- one request status or one console error is enough to explain the behavior
|
||||
- deeper debugging would not change the next action
|
||||
|
||||
## Stop conditions
|
||||
|
||||
Stop the recovery loop and report the limitation when:
|
||||
|
||||
- repeated fresh snapshots still do not produce a usable target
|
||||
- page ownership or page identity is now ambiguous
|
||||
- the current page no longer preserves the evidence needed for a safe retry
|
||||
- deeper console or network inspection would not change the next browser decision
|
||||
|
||||
If the stronger explanation is now auth, soft 404, or anti-automation friction, return to the skill entrypoint and load the more specific reference from there instead of stretching this file into a general classifier.
|
||||
|
||||
## Boundary
|
||||
|
||||
This file is for recovery inside an already-classified browser run.
|
||||
|
||||
It does not own:
|
||||
|
||||
- route selection
|
||||
- site-pattern discipline
|
||||
- control-plane confirmation discipline
|
||||
- capability proof
|
||||
|
||||
Once the recovery state is understood, return to the skill entrypoint for any additional specialized reference instead of turning this file into a second routing hub.
|
||||
@@ -0,0 +1,113 @@
|
||||
# Control-Plane Workflows
|
||||
|
||||
Load this reference only after the task is already `browser-required` and the target is a logged-in dashboard, admin surface, CMS, editor, or other control-plane workflow.
|
||||
|
||||
This file is for save, publish, update, upload, and settings-style work inside authenticated browser surfaces.
|
||||
|
||||
## Core posture
|
||||
|
||||
Control-plane work is not generic browsing. The page may look ordinary while every meaningful action changes real state.
|
||||
|
||||
Start by classifying the task as one of these:
|
||||
|
||||
- read-only inspection
|
||||
- state-changing action
|
||||
|
||||
Read-only inspection can usually stop once the requested evidence is visible and stable.
|
||||
|
||||
State-changing work must not stop at "the click happened." It needs stronger confirmation.
|
||||
|
||||
## Write-safety rule
|
||||
|
||||
For state-changing actions, require:
|
||||
|
||||
- one visible confirmation signal
|
||||
- plus one structural proof
|
||||
|
||||
Good visible confirmation signals include:
|
||||
|
||||
- toast or banner text
|
||||
- a success badge or status chip
|
||||
- a changed button state such as `Saved`, `Published`, or disabled busy state resolving to ready
|
||||
|
||||
Good structural proofs include:
|
||||
|
||||
- URL or route change that matches the intended result
|
||||
- a stable state badge or saved timestamp after a fresh snapshot
|
||||
- a newly visible row, card, or asset in the expected container
|
||||
- one confirming network result when visible evidence is ambiguous
|
||||
|
||||
For destructive or externally visible actions such as publish, delete, send, or live settings changes, do not accept a single weak signal.
|
||||
|
||||
## Standard post-action sequence
|
||||
|
||||
After a save, publish, update, or upload action:
|
||||
|
||||
1. Refresh visible understanding with a fresh snapshot.
|
||||
2. Check for one visible success signal.
|
||||
3. Check for one structural proof that the state actually changed.
|
||||
4. Inspect network or console only if the visible result is still ambiguous.
|
||||
|
||||
If the task is destructive or user-visible outside the current page, do not report success until both signals agree.
|
||||
|
||||
## Save and publish flows
|
||||
|
||||
For save or publish work:
|
||||
|
||||
- capture the relevant pre-action state first when the before/after difference matters
|
||||
- trigger the action once
|
||||
- wait for the smallest reliable confirmation signal
|
||||
- re-snapshot before deciding the action succeeded
|
||||
|
||||
Do not stack repeated save or publish clicks just because the page looks busy.
|
||||
|
||||
If the page exposes both a draft state and a published state, name the state explicitly in notes and final output.
|
||||
|
||||
## Upload flows
|
||||
|
||||
Uploads inside control planes often mix hidden inputs, custom triggers, and delayed confirmation.
|
||||
|
||||
Use the existing upload protocol from the live-browser playbook as the base behavior.
|
||||
|
||||
Use the selector bridge when:
|
||||
|
||||
- the upload control is present in the DOM but not clearly actionable from the snapshot
|
||||
- the file input exists but the visible trigger is custom
|
||||
- MCP-native upload is the right action but the current snapshot does not surface a usable target
|
||||
|
||||
After upload, do not stop at "the file chooser accepted the file." Confirm that the control plane reflects the uploaded asset in the intended place.
|
||||
|
||||
Typical structural proofs after upload include:
|
||||
|
||||
- thumbnail or filename appears
|
||||
- asset row appears in a table or picker
|
||||
- status changes from pending to ready
|
||||
|
||||
## Ambiguous outcomes
|
||||
|
||||
If the UI says success but the structural proof is missing:
|
||||
|
||||
- distrust the success signal
|
||||
- refresh understanding
|
||||
- inspect the relevant request or console evidence only if needed
|
||||
|
||||
If the UI does not show success but the structural proof is already present:
|
||||
|
||||
- treat the action as provisionally successful
|
||||
- report the mismatch instead of retrying blindly
|
||||
|
||||
Do not turn ambiguous state into brute-force retries.
|
||||
|
||||
## Read-only bias for high-risk surfaces
|
||||
|
||||
For social platforms, production dashboards, billing controls, or any surface where repeated mutations carry risk, default to the smallest read-only investigation that can still answer the question.
|
||||
|
||||
Escalate from read-only to state-changing actions only when the task explicitly requires it.
|
||||
|
||||
If the workflow is plausibly in a defensive or rate-limited state, return to the skill entrypoint and load the anti-automation reference from there.
|
||||
|
||||
## Boundary
|
||||
|
||||
This file defines confirmation discipline for authenticated control planes. It does not replace the ordinary browser protocol, upload mechanics, or selector bridge technique.
|
||||
|
||||
For the underlying page loop, uploads, and action targeting, return to the skill entrypoint and load the ordinary references instead of treating this file as a second hub.
|
||||
@@ -0,0 +1,80 @@
|
||||
# Debug Handoff
|
||||
|
||||
Load this reference only after the task is already `browser-required` and the user indicates that a manual browser debugging context is already open.
|
||||
|
||||
This file is for handoff from an active debugging session, not for generic browser triage from scratch.
|
||||
|
||||
## Scope
|
||||
|
||||
Use this reference when the user says or clearly implies any of the following:
|
||||
|
||||
- they already selected an element in an inspector panel such as Elements
|
||||
- they already selected a request in a network panel
|
||||
- they already have the broken page open and want the agent to continue from there
|
||||
- they want investigation to start from the current live session rather than from a fresh repro
|
||||
|
||||
If the user has not indicated an active debugging context, stay with the normal browser workflow.
|
||||
|
||||
## Core rule
|
||||
|
||||
Prefer handoff from the current debugging context over replaying the entire issue.
|
||||
|
||||
The default order is:
|
||||
|
||||
1. Reuse the current browser session and page if possible.
|
||||
2. Reuse the current debugging context if the host exposes it.
|
||||
3. Re-anchor from the current page state if the debugging context is only partially exposed.
|
||||
4. Reproduce from scratch only when the current context is missing, stale, or insufficient.
|
||||
|
||||
Do not jump straight to replaying the flow just because reproduction seems familiar.
|
||||
|
||||
## Selected element flow
|
||||
|
||||
When the user says they already selected an element in an inspector panel:
|
||||
|
||||
1. Stay on the current page or the closest current page match instead of opening a fresh repro page.
|
||||
2. Read current visible state first with the normal snapshot path.
|
||||
3. If the host exposes the current element selection directly, use that selection as the starting anchor.
|
||||
4. If the host does not expose the selection directly, re-anchor from the current page state, not from a brand-new reproduction flow.
|
||||
5. Only recreate the issue if the current DOM no longer contains a trustworthy anchor for the selected area.
|
||||
|
||||
The selected element is a starting clue, not a guarantee that the exact node is still valid. Favor the smallest re-anchoring step that preserves the user's current context.
|
||||
|
||||
## Selected request flow
|
||||
|
||||
When the user says they already selected a request in a network panel:
|
||||
|
||||
1. Prefer the currently selected request if the host exposes it.
|
||||
2. If the host does not expose the current selection directly, inspect the current page session before replaying the action.
|
||||
3. Use request metadata already visible in the current session to narrow the target request.
|
||||
4. Re-trigger the action only if the current request cannot be identified or no longer exists.
|
||||
|
||||
If one concrete request already explains the failure, stop there. Do not recreate the request just to prove the same point twice.
|
||||
|
||||
## When to reproduce anyway
|
||||
|
||||
Reproduce from scratch only when one of these is true:
|
||||
|
||||
- the current page or tab can no longer be identified reliably
|
||||
- the selected element or request is stale and cannot be re-anchored from current state
|
||||
- the host does not expose enough of the current debugging context to continue safely
|
||||
- the bug requires a fresh transition or timing sequence that the current page state no longer preserves
|
||||
|
||||
When you do reproduce, keep it minimal. Recreate only the smallest sequence needed to regain the missing evidence.
|
||||
|
||||
## Stop conditions
|
||||
|
||||
Stop treating this as a handoff and report the limitation when:
|
||||
|
||||
- there is no current page match for the user's described debugging context
|
||||
- the user says a selection exists but the host exposes no selection signal and the current page provides no trustworthy anchor
|
||||
- the selected request or selected element appears stale relative to the current page state
|
||||
- the browser session has drifted too far from the original debugging context to support reliable continuation
|
||||
|
||||
In those cases, say that the active debugging context could not be reused and that a minimal fresh repro is now required.
|
||||
|
||||
## Boundary
|
||||
|
||||
This file changes where investigation starts. It does not replace the ordinary live-browser protocol.
|
||||
|
||||
For page actions, snapshots, uploads, or recovery, return to the skill entrypoint and load the ordinary browser protocol from there instead of turning this file into a second workflow hub.
|
||||
@@ -0,0 +1,71 @@
|
||||
# Deep DOM
|
||||
|
||||
Load this reference only after the task has already been classified as `browser-required`. This file is the authority for iframe, Shadow DOM, collapsed content, and lazy-loaded evidence.
|
||||
|
||||
## Scope
|
||||
|
||||
Use this reference when the evidence depends on any of these structures:
|
||||
|
||||
- same-origin iframe
|
||||
- Shadow DOM
|
||||
- collapsed or `details`-hidden content
|
||||
- lazy-loaded content that appears only after a state change
|
||||
|
||||
## Fixed operating order
|
||||
|
||||
1. Create or reuse one task-owned page.
|
||||
2. Take a fresh snapshot and confirm the main container for the target page.
|
||||
3. Locate the iframe host, shadow host, collapsed container, and lazy zone before extracting anything.
|
||||
4. Extract each token together with the evidence location that produced it.
|
||||
5. For lazy-loaded content, use the minimum trigger needed and record the retry count.
|
||||
6. Once all evidence is collected, stop and clean up only clearly task-owned pages.
|
||||
|
||||
## same-origin iframe
|
||||
|
||||
Start by confirming whether the iframe is same-origin enough to inspect from the current page.
|
||||
|
||||
- Prefer visible rendered evidence first when the iframe already exposes the needed text.
|
||||
- If visible evidence is insufficient, read from `contentDocument` or equivalent same-origin DOM access.
|
||||
- Record both the iframe host and the inner evidence location so the later scorer can verify where the token came from.
|
||||
|
||||
If the iframe is cross-origin and the task still needs its internals, stop and report that boundary rather than inventing a DOM path.
|
||||
|
||||
## Shadow DOM
|
||||
|
||||
Shadow DOM is not a reason to skip the visible layer.
|
||||
|
||||
- First confirm what the user-visible host already proves.
|
||||
- Enter `shadowRoot` only when the visible state is ambiguous or the token exists only in component internals.
|
||||
- Keep the evidence path specific, such as host selector plus `shadowRoot` plus the terminal node or attribute.
|
||||
|
||||
## Collapsed content
|
||||
|
||||
Collapsed content should not be expanded by default.
|
||||
|
||||
- First try structural or DOM-level reading from the collapsed container itself.
|
||||
- Only expand the section if the structure read is insufficient to prove the token.
|
||||
- If expansion is necessary, do it once, capture the token, and stop.
|
||||
|
||||
This keeps the action count low and avoids treating every collapsed section as an interaction problem.
|
||||
|
||||
## Lazy-loaded content
|
||||
|
||||
Lazy-loaded evidence must follow a minimum-trigger strategy.
|
||||
|
||||
- Capture the initial state first.
|
||||
- Use one deliberate trigger only: usually one targeted scroll or one specific state change.
|
||||
- Re-read the lazy zone immediately after the trigger.
|
||||
- Record the minimum retries needed as an integer. If the first trigger worked, the retry count is `1` trigger and `0` extra retries.
|
||||
|
||||
Do not keep scrolling just because the page moved. Once the token appears, stop.
|
||||
|
||||
## Evidence discipline
|
||||
|
||||
For each token, record:
|
||||
|
||||
- token kind
|
||||
- token value
|
||||
- where it was obtained from
|
||||
- which evidence files prove it
|
||||
|
||||
This reference is about extraction discipline, not about generic cleanup, routing, or login judgment. Those remain in the entrypoint and the live-browser playbook.
|
||||
@@ -0,0 +1,82 @@
|
||||
# Media Inspection
|
||||
|
||||
Load this reference only after the task is already `browser-required` and the important evidence is in an image, audio clip, or video rather than ordinary page text.
|
||||
|
||||
The goal is to inspect the media with the lightest reliable method, not to default to broad screenshots.
|
||||
|
||||
## Extraction ladder
|
||||
|
||||
Start with the page-level media state and only escalate when that state is incomplete.
|
||||
|
||||
Preferred ladder:
|
||||
|
||||
1. Inspect the page-level media element and surrounding metadata.
|
||||
2. Inspect discovered `<source>` URLs or media resource references.
|
||||
3. Move to the media resource itself only when that gives a better answer than the page can.
|
||||
|
||||
That order keeps you aligned with the user-visible context while still giving you a path to more direct evidence when the page exposes it.
|
||||
|
||||
## Image, audio, and video handling
|
||||
|
||||
For images:
|
||||
|
||||
- confirm the visible container first
|
||||
- inspect `src`, `srcset`, poster-like metadata, or linked media URLs when they matter
|
||||
- use a screenshot only when rendered presentation is the evidence
|
||||
|
||||
For audio:
|
||||
|
||||
- inspect the player element, source URL, current playback state, and nearby labels or captions
|
||||
- prefer direct source extraction when the page exposes it and the source itself answers the task better
|
||||
|
||||
For video:
|
||||
|
||||
- inspect `currentSrc`, `duration`, `currentTime`, `paused`, and source URLs with `evaluate_script`
|
||||
- prefer controlled seeking through DOM state instead of manual scrubbing through unstable controls
|
||||
- take targeted screenshots after deliberate seeks when the important evidence is a specific frame
|
||||
|
||||
Keep these facts in mind while inspecting media-heavy pages:
|
||||
|
||||
- content can already exist in the DOM while still being off-screen or visually hidden
|
||||
- Shadow DOM and iframe boundaries can hide the real media host
|
||||
- lazy-loaded media may not exist until the relevant region has been revealed or scrolled
|
||||
- a page saying "not found" or "not available" can reflect the wrong route shape, missing parameters, or anti-automation behavior rather than true absence
|
||||
- opening too many pages too quickly can look more automated than a smaller, deliberate page set
|
||||
|
||||
## Video seek and frame capture
|
||||
|
||||
For video-heavy tasks, treat the `<video>` element as the primary evidence source before escalating to full-page screenshots.
|
||||
|
||||
Use this sequence:
|
||||
|
||||
1. Confirm the player location and whether surrounding controls matter.
|
||||
2. Inspect the video element's DOM state.
|
||||
3. Seek deliberately with DOM-controlled state changes.
|
||||
4. Capture a targeted screenshot only after the player is at the intended frame.
|
||||
|
||||
This avoids blind scrubbing and produces cleaner evidence than full-page capture at arbitrary playback states.
|
||||
|
||||
## When not to screenshot
|
||||
|
||||
Do not default to screenshots when:
|
||||
|
||||
- the page already exposes the media URL directly
|
||||
- the answer is in metadata or DOM state rather than the rendered frame
|
||||
- a direct media source read would be more precise than page capture
|
||||
|
||||
Use screenshots when:
|
||||
|
||||
- the rendered frame itself is the evidence
|
||||
- overlap, crop, playback controls, or layout context matter
|
||||
- the task is about what the user actually sees at a specific moment
|
||||
|
||||
Choose the narrowest screenshot that proves the point. Element-level or tightly framed screenshots are usually better than full-page capture for media work.
|
||||
|
||||
## When media inspection turns ambiguous
|
||||
|
||||
If media inspection stops being straightforward, do not build a second recovery workflow here.
|
||||
|
||||
- switch to the recovery reference when the problem is stale state, ambiguous interaction results, or console / network escalation
|
||||
- switch to the deep-DOM reference when the real blocker is nested frames, Shadow DOM, collapsed structure, or delayed loading
|
||||
|
||||
When you change evidence sources, say so explicitly in your notes. A reader should be able to tell whether the conclusion came from the page-level player state or from the underlying media resource.
|
||||
@@ -0,0 +1,123 @@
|
||||
# Parallel Browser Ownership
|
||||
|
||||
Load this reference only after the task is already `browser-required` and browser work should be split across multiple task-owned pages or multiple browser-capable agents.
|
||||
|
||||
The goal is to preserve concurrency benefits without creating cross-agent page collisions.
|
||||
|
||||
## Ownership model
|
||||
|
||||
Default to an ownership-first browser model.
|
||||
|
||||
The rule is simple: one owner per page.
|
||||
|
||||
This host environment can behave like a mixed model:
|
||||
|
||||
- task-owned pages created by one agent may still appear in the shared page pool
|
||||
- different agents may not agree on the same selected page
|
||||
|
||||
Treat that as shared page visibility plus partially isolated selection state unless you have better evidence in the current run.
|
||||
|
||||
The operating consequence is that page visibility is not permission to operate the page. Even if another agent can see a page in `list_pages`, it should not select, mutate, or close that page unless it is the explicit owner.
|
||||
|
||||
What still makes ownership discipline necessary:
|
||||
|
||||
- another agent can still see a page that you created
|
||||
- cleanup ownership becomes ambiguous once multiple agents start touching the same page
|
||||
- stale `uid`s remain a risk if two agents interact with one page and one of them rerenders it
|
||||
|
||||
## Page ledger fields
|
||||
|
||||
Whenever a live browser stack is in use, maintain a lightweight page ledger in working memory. Track at least:
|
||||
|
||||
- a stable page handle
|
||||
- the MCP `pageId`
|
||||
- the current URL or identifying title
|
||||
- the page owner
|
||||
- the `isolatedContext`
|
||||
- whether the page was created by you
|
||||
- whether it should be closed at task exit
|
||||
|
||||
This ledger is session-local working state, not runtime state inside the application under test.
|
||||
|
||||
Use the ledger to answer three questions quickly:
|
||||
|
||||
1. Which pages do I own?
|
||||
2. Which page should I select before acting?
|
||||
3. Which pages am I allowed to close at the end?
|
||||
|
||||
## `isolatedContext` rules
|
||||
|
||||
Create task-owned pages deliberately. Use a distinct `isolatedContext` for each browser owner unless you have verified that the workflow requires shared auth state or shared storage.
|
||||
|
||||
Use isolated contexts when:
|
||||
|
||||
- you want clean ownership boundaries
|
||||
- the investigation does not depend on inheriting another task-owned page's browser state
|
||||
- you want cleanup to remain unambiguous
|
||||
|
||||
Be careful with authenticated control planes. Some sites behave as if `isolatedContext` also isolates auth state. When that happens:
|
||||
|
||||
- keep the user-owned page read-only
|
||||
- open one non-isolated child page for safe, read-only investigation if needed
|
||||
- avoid destructive actions until the auth behavior is understood
|
||||
- prefer overview, activity, audit, or other read-only tabs while validating the behavior
|
||||
- record the verified exception in the matching site-pattern note
|
||||
|
||||
Do not assume this exception globally. Treat it as domain-specific until verified.
|
||||
|
||||
## Parallel delegation rules
|
||||
|
||||
Parallel browser work is a good fit when:
|
||||
|
||||
- the task contains several independent targets
|
||||
- each target can be researched without depending on another target's in-page state
|
||||
- the subtasks are large enough to justify the delegation cost
|
||||
|
||||
Parallel browser work is a bad fit when:
|
||||
|
||||
- one page has evolving local state that later steps depend on
|
||||
- step 2 depends directly on what step 1 discovered on the same page
|
||||
- the task is small enough that delegation overhead outweighs any gain
|
||||
|
||||
Good splits:
|
||||
|
||||
- one agent per independent page or domain
|
||||
- one browser owner plus supporting non-browser agents for search, synthesis, or candidate comparison
|
||||
- one browser owner validating controls while another browser owner inspects a separate target page
|
||||
|
||||
Bad splits:
|
||||
|
||||
- two agents clicking around the same SPA tab
|
||||
- one agent taking snapshots while another mutates the same page
|
||||
- shared cleanup responsibility with no explicit owner
|
||||
|
||||
When delegating, describe:
|
||||
|
||||
- the goal
|
||||
- the evidence target
|
||||
- the success condition
|
||||
|
||||
Do not over-constrain the sub-agent with a brittle step-by-step browser script unless the sequence itself is the task.
|
||||
|
||||
Useful responsibility split:
|
||||
|
||||
- browser page owners create pages, select pages, take snapshots, and perform page mutations on their own task-owned pages
|
||||
- supporting agents handle web search, source comparison, summarization, and structured follow-up requests without touching the page
|
||||
|
||||
## Do-not-touch rules
|
||||
|
||||
Never:
|
||||
|
||||
- select a page owned by another agent
|
||||
- mutate a page owned by another agent
|
||||
- close a page owned by another agent
|
||||
- assume the currently selected page is globally shared state
|
||||
- treat shared page visibility as shared ownership
|
||||
|
||||
If another agent needs a browser action, hand it off request-style instead of sharing the page. Good requests look like:
|
||||
|
||||
- "Open this URL in your own task page and confirm whether an upload control exists."
|
||||
- "Inspect this page and tell me whether selector bridge is necessary."
|
||||
- "Submit this form in your own page and report the confirmation text."
|
||||
|
||||
That keeps ownership crisp, stale `uid` risk low, and cleanup safe.
|
||||
@@ -0,0 +1,101 @@
|
||||
# Selector Bridge
|
||||
|
||||
`use-my-browser` keeps a lot of selector intuition, but the active live-browser stack acts on snapshot `uid`s. The selector bridge converts selector knowledge into MCP-native interaction without rebuilding a local executor.
|
||||
|
||||
Load this reference only when selector knowledge must be translated into snapshot-guided MCP actions such as `click` or `upload_file`.
|
||||
|
||||
## Why prefer MCP-native clicks
|
||||
|
||||
MCP-native clicks and uploads should win whenever possible because they act on the page as the live-browser stack understands it:
|
||||
|
||||
- they operate on the current accessibility tree rather than an assumed DOM reference
|
||||
- they behave more like user interaction than `el.click()`
|
||||
- they are better aligned with `upload_file`
|
||||
- they keep page understanding and action in the same snapshot-driven protocol
|
||||
|
||||
Snapshot `uid`s come from the accessibility tree, so bridge strategies that produce stable accessible labels are more reliable than raw DOM-only markers.
|
||||
|
||||
## The six-step bridge
|
||||
|
||||
1. Use `evaluate_script` to locate the target element with the selector knowledge you already have.
|
||||
2. Add a temporary unique bridge marker such as a task-specific `aria-label`, or a `data-*` marker paired with an accessible label you can later find in the snapshot.
|
||||
3. Run `take_snapshot` to refresh the accessibility tree.
|
||||
4. Find the matching `uid` in the snapshot.
|
||||
5. Call `click(uid)` or `upload_file(uid)` with the MCP-native target.
|
||||
6. Remove the temporary marker with `evaluate_script` once the action is complete.
|
||||
|
||||
## Marker strategy
|
||||
|
||||
Prefer a temporary `aria-label` when possible because the snapshot is accessibility-tree driven.
|
||||
|
||||
Use a `data-*` marker when:
|
||||
|
||||
- you need a DOM-only breadcrumb for cleanup
|
||||
- the page already derives accessible text from nearby content
|
||||
- you plan to use `evaluate_script` once more to confirm which node the snapshot entry refers to
|
||||
|
||||
Keep the marker:
|
||||
|
||||
- unique per task
|
||||
- narrow in scope
|
||||
- easy to remove
|
||||
|
||||
## Example bridge flow
|
||||
|
||||
1. Use `evaluate_script` to find `input[type="file"]` or a custom upload trigger.
|
||||
2. Inject a temporary `aria-label` such as `umb-task-42-upload`.
|
||||
3. Run `take_snapshot`.
|
||||
4. Find the element whose accessible name is `umb-task-42-upload`.
|
||||
5. Use `upload_file(uid)` or `click(uid)`.
|
||||
6. Remove the temporary marker.
|
||||
|
||||
## When bridging is a good fit
|
||||
|
||||
Bridge selectors into snapshot `uid`s when:
|
||||
|
||||
- you already know a reliable CSS selector from site experience
|
||||
- the page uses opaque class names but still exposes accessible controls after annotation
|
||||
- you need `upload_file`, especially when the file input is present in the DOM but not clearly exposed in the snapshot
|
||||
- you want a real MCP-native click instead of a script-level click
|
||||
|
||||
File upload is a first-class bridge case. In practice, upload controls are a priority bridge case. If the snapshot does not expose an actionable file input or upload trigger, prefer building the bridge immediately instead of retrying random clicks or falling back to DOM-only upload logic.
|
||||
|
||||
## When to skip the bridge and stay in `evaluate_script`
|
||||
|
||||
Stay in `evaluate_script` when the goal is understanding or extraction rather than user-like interaction, for example:
|
||||
|
||||
- reading hidden data structures
|
||||
- walking Shadow DOM or iframe trees
|
||||
- extracting generated links or media URLs
|
||||
- inspecting canvas-adjacent state
|
||||
- cleaning up temporary bridge markers
|
||||
- handling pages where the accessibility tree does not expose a useful action target even after annotation
|
||||
|
||||
Do not build a bridge just to read text or metadata. Bridge for actions such as click or upload, not for extraction.
|
||||
|
||||
Do not use the selector bridge when the problem is fundamentally a DOM-read or DOM-write that `evaluate_script` can solve directly.
|
||||
|
||||
Do not treat `type_text` as a bridge substitute. The bridge solves target acquisition for MCP-native actions; `type_text` solves input-mode choice after the correct target is already focused.
|
||||
|
||||
## Failure recovery
|
||||
|
||||
If the bridge fails:
|
||||
|
||||
- re-run `select_page(pageId, bringToFront=false)`
|
||||
- take a new snapshot
|
||||
- confirm that the temporary marker still exists
|
||||
- prefer a fresh `aria-label` marker if the old one was lost in a rerender
|
||||
- if the page rerendered, rebuild the bridge from the selector instead of trusting the old marker
|
||||
- remove stale bridge markers before creating a fresh one when possible
|
||||
- fall back to pure `evaluate_script` only when MCP-native interaction is not viable for that page
|
||||
|
||||
Terminate the bridge attempt and stay in `evaluate_script` when:
|
||||
|
||||
- repeated fresh snapshots still do not expose a usable `uid`
|
||||
- the annotated control is present in the DOM but never becomes actionable in the accessibility tree
|
||||
- the task is really extraction, not interaction
|
||||
- the page keeps rerendering away the marker faster than a stable bridge can be established
|
||||
|
||||
Say the decision out loud in run notes when it matters: rebuild the bridge if the page rerendered, and terminate the bridge attempt if fresh snapshots still never surface a usable `uid`.
|
||||
|
||||
Network and console inspection are also outside the bridge itself. Use them after the interaction when page behavior is ambiguous, not as part of the bridge construction flow.
|
||||
@@ -1,186 +0,0 @@
|
||||
# Session Playbook
|
||||
|
||||
This playbook holds the detailed patterns that make the live browser session useful without becoming intrusive.
|
||||
|
||||
## 1. Reuse the Current Session Deliberately
|
||||
|
||||
Prefer the live Chrome DevTools session when the task depends on:
|
||||
|
||||
- Signed-in state
|
||||
- Current cookies or app context
|
||||
- An already selected Elements or Network target
|
||||
- Existing app state that would be expensive to reproduce
|
||||
|
||||
Start by checking what is already open:
|
||||
|
||||
- `list_pages` to understand available pages
|
||||
- `select_page` to move into the right one
|
||||
- `take_snapshot` to inspect current structure before interacting
|
||||
|
||||
Use the user's existing page when their current state is the point of the task. Otherwise, create or select your own working page so you do not disturb their main tab.
|
||||
|
||||
If the live browser session is expected but unavailable:
|
||||
|
||||
- say clearly that you do not currently have the live browser session
|
||||
- fall back to a public-web or Playwright path only if that still serves the goal
|
||||
- explain that a clean fallback browser is not equivalent to the user's current signed-in session
|
||||
|
||||
## 2. Tab Hygiene
|
||||
|
||||
### Prefer non-destructive behavior
|
||||
|
||||
- Do not close pages you did not open.
|
||||
- Do not reload the user's page just because it is convenient.
|
||||
- Do not bring pages to the front unless the task or user requires it.
|
||||
- If experimentation may be disruptive, open a separate page and keep the original intact.
|
||||
|
||||
### When to use the active page
|
||||
|
||||
Use the active page directly when:
|
||||
|
||||
- The user explicitly wants you to continue from their current debugging state.
|
||||
- The relevant request or element is already selected.
|
||||
- Reproducing the state elsewhere would lose the point of the task.
|
||||
|
||||
## 3. DOM-First Extraction
|
||||
|
||||
Prefer structured evidence over screenshots:
|
||||
|
||||
1. `take_snapshot` for the accessible page structure and selected-element context
|
||||
2. `evaluate_script` for data, state, attributes, computed values, and DOM traversal
|
||||
3. Network and console tools when the answer may not be visible in the DOM
|
||||
4. `take_screenshot` only when rendered pixels actually matter
|
||||
|
||||
### Good DOM-first cases
|
||||
|
||||
- Hidden text already mounted in the DOM
|
||||
- Link targets and image sources
|
||||
- Data attributes, ARIA state, classes, and inline styles
|
||||
- Video metadata like `currentTime`, `duration`, and pause state
|
||||
- Values inside open shadow roots or same-origin page structures reachable from script
|
||||
|
||||
### When DOM-first may fail
|
||||
|
||||
- Cross-origin iframes or inaccessible embedded contexts
|
||||
- Canvas-only or screenshot-only content
|
||||
- Visual bugs where the pixels matter more than the markup
|
||||
|
||||
If the DOM route stalls, switch to a more suitable layer instead of forcing OCR or repeated snapshots.
|
||||
|
||||
### Site-generated links beat guessed URLs
|
||||
|
||||
If the page already exposes a link, image URL, or media URL:
|
||||
|
||||
- prefer the exact site-generated URL
|
||||
- preserve the query string and other context unless you know they are optional
|
||||
- treat "manually simplified" URLs as suspect if the site starts returning misleading errors
|
||||
|
||||
## 4. GUI vs Programmatic Interaction
|
||||
|
||||
There are two main interaction styles:
|
||||
|
||||
- Programmatic: direct DOM reads and writes through `evaluate_script`, fast navigation, and structured extraction
|
||||
- GUI-like: `click`, `fill`, `hover`, keyboard input, scrolling, and screenshots that behave more like a user
|
||||
|
||||
Prefer programmatic work when:
|
||||
|
||||
- The data already exists in the page
|
||||
- You need reliable extraction rather than user simulation
|
||||
- Direct DOM access is simpler than replaying UI steps
|
||||
|
||||
Prefer GUI-style interaction when:
|
||||
|
||||
- A real user gesture matters
|
||||
- The site reacts poorly to direct DOM manipulation
|
||||
- The page needs scrolling, expansion, hovering, or upload interactions to reveal the real state
|
||||
|
||||
If a site resists one mode, switch rather than retrying the same tactic.
|
||||
|
||||
If the UI looks like a blocker, first ask whether it really blocks the data. Sometimes the content is already present in the DOM or network layer and the visible interaction is only a presentation detail.
|
||||
|
||||
## 5. Lazy Loading, Hidden Data, and Media
|
||||
|
||||
### Lazy-loaded pages
|
||||
|
||||
- Scroll before concluding content is missing
|
||||
- Re-snapshot after major state changes
|
||||
- Look for content URLs, placeholders, or hydration data before resorting to screenshots
|
||||
- Treat "empty" or "not found" UI states carefully when the route or parameters may be wrong
|
||||
|
||||
### Images and media
|
||||
|
||||
- Prefer extracting image and media URLs from the DOM or page scripts
|
||||
- Use screenshots when the rendered image itself is the subject
|
||||
- If a file URL is public and directly downloadable, prefer a raw fetch over full-page screenshot analysis
|
||||
|
||||
### Video sampling
|
||||
|
||||
Use `evaluate_script` on the relevant `<video>` element to:
|
||||
|
||||
- Inspect `currentTime`, `duration`, and playback state
|
||||
- Seek to a target timestamp when the page allows it
|
||||
- Pause on a representative frame
|
||||
|
||||
Then capture the rendered frame with `take_screenshot` if visual analysis is needed.
|
||||
|
||||
## 6. Login Handling
|
||||
|
||||
The live browser session is valuable because the user may already be signed in.
|
||||
|
||||
### Default rule
|
||||
|
||||
Try to access the target through the live browser session first. If the data is available, keep going without making login a separate task.
|
||||
|
||||
### When to pause and ask
|
||||
|
||||
Pause only when:
|
||||
|
||||
- The needed content is clearly blocked by authentication
|
||||
- The current live session does not already grant access
|
||||
- Logging in inside the user's real Chrome would unlock the task
|
||||
|
||||
In that case, ask the user to log in in Chrome and continue after they confirm. Do not default to reproducing the login flow in an isolated browser unless the user asked for that.
|
||||
|
||||
## 7. DevTools Handoff
|
||||
|
||||
### Selected element workflow
|
||||
|
||||
- Start with `take_snapshot`
|
||||
- Use `evaluate_script` for nearby DOM state, computed values, or targeted extraction
|
||||
- Use interaction tools only after understanding the current structure
|
||||
|
||||
### Selected network request workflow
|
||||
|
||||
- Start with `get_network_request` without `reqid`
|
||||
- Inspect status, headers, payloads, and failure text
|
||||
- Broaden to `list_network_requests` only if the surrounding traffic matters
|
||||
|
||||
## 8. Public-Source Verification
|
||||
|
||||
When the task is about truth, not interaction:
|
||||
|
||||
- Prefer primary sources over copied reporting
|
||||
- Use `web` for discovery and citations
|
||||
- Attach to the live browser session only when the source is dynamic, authenticated, or otherwise inaccessible from the public-web path
|
||||
|
||||
The browser is not automatically more authoritative than the public-web path. Use the right layer for the claim you need to support.
|
||||
|
||||
## 9. Troubleshooting Fallbacks
|
||||
|
||||
If the live browser session approach is blocked:
|
||||
|
||||
- Check whether the target actually needs the live browser session
|
||||
- Check whether a cheaper processed read or raw fetch path can answer the question first
|
||||
- Consider whether a public `web` path is sufficient after all
|
||||
- Use Playwright if the task wants a separate clean browser context
|
||||
- Mention `--autoConnect` or `--browser-url` only if the issue is truly about session attachment or Chrome DevTools MCP configuration
|
||||
|
||||
## 10. Parallel Research
|
||||
|
||||
When several targets are independent:
|
||||
|
||||
- batch `web` lookups before reaching for agents
|
||||
- keep each browser investigation in its own page context
|
||||
- if the user explicitly asked for parallel agent work, frame each delegated task around the goal and success condition instead of hard-coding the tool layer too early
|
||||
|
||||
Do not split work that depends on one evolving page state.
|
||||
@@ -1,56 +1,100 @@
|
||||
# Site Patterns
|
||||
|
||||
This folder is for validated, reusable browsing notes for specific domains.
|
||||
Domain notes under this directory store reusable, verified operating knowledge for specific sites. They are for facts that future runs should not have to rediscover.
|
||||
|
||||
Add a file here only when a pattern has been confirmed in real use. The point is to preserve facts that help future sessions avoid repeated trial and error, not to collect guesses.
|
||||
Store one note per domain as `references/site-patterns/{domain}.md`, and keep the filename aligned with the `domain` value in frontmatter.
|
||||
|
||||
## Workflow
|
||||
## When to Create a Site Pattern Note
|
||||
|
||||
1. If the target domain already has a note, read it before browsing.
|
||||
2. Treat the note as a strong hint, not as guaranteed truth.
|
||||
3. If you confirm a new reusable pattern, update the note after the task.
|
||||
4. Write facts, proven patterns, and traps only after they are validated.
|
||||
Create or update a domain note when you have verified site-specific behavior that changes how the skill should operate on that site, such as:
|
||||
|
||||
## What belongs here
|
||||
- login or session inheritance quirks
|
||||
- stable route shapes or required query parameters
|
||||
- predictable anti-automation friction
|
||||
- reliable selectors or interaction patterns
|
||||
- repeatable browser workflows that are specific to the domain
|
||||
|
||||
- Verified URL or navigation patterns that matter for access
|
||||
- Known login or session requirements
|
||||
- Proven extraction tactics for that site
|
||||
- Known traps, false error states, or brittle interaction patterns
|
||||
Do not create notes for one-off observations that have not been verified.
|
||||
|
||||
## What does not belong here
|
||||
## Verified Facts Only
|
||||
|
||||
- Unconfirmed hunches
|
||||
- Site-specific notes that were only true once and cannot be repeated
|
||||
- Generic browser advice that already belongs in the main skill
|
||||
Record only verified facts, not guesses, intuitions, or "probably works" observations.
|
||||
|
||||
## File Template
|
||||
Good note content:
|
||||
|
||||
Create one file per domain:
|
||||
- "Opening a task page with `isolatedContext` loses the authenticated session on this domain."
|
||||
- "The detail page is reachable only through the DOM-generated `href`; hand-built URLs produce a soft 404."
|
||||
|
||||
Bad note content:
|
||||
|
||||
- "This site might use React."
|
||||
- "Looks like the upload dialog is flaky."
|
||||
|
||||
If the behavior is not yet verified, leave it out.
|
||||
|
||||
## Required Frontmatter
|
||||
|
||||
Every domain note should start with:
|
||||
|
||||
```markdown
|
||||
---
|
||||
domain: example.com
|
||||
aliases:
|
||||
- Example
|
||||
updated: 2026-03-28
|
||||
aliases: [Example]
|
||||
updated: 2026-04-05
|
||||
confidence: high
|
||||
evidence: DOM href worked; hand-built URL soft-404ed
|
||||
---
|
||||
|
||||
## Platform Traits
|
||||
|
||||
Facts about rendering, auth, navigation, or anti-automation behavior.
|
||||
|
||||
## Proven Patterns
|
||||
|
||||
Concrete paths, selectors, workflows, or extraction techniques that worked.
|
||||
|
||||
## Known Traps
|
||||
|
||||
Things that look like product behavior but are really access-path problems, stale state, or misleading errors.
|
||||
```
|
||||
|
||||
## Writing Rules
|
||||
Use the real domain as `domain`. Keep `aliases` short and practical. Use `YYYY-MM-DD` for `updated`, and change it when the note changes meaningfully.
|
||||
|
||||
- Keep entries short and factual.
|
||||
- Prefer reproducible facts over advice.
|
||||
- Update the date when you materially revise the note.
|
||||
Use `confidence` to express how hard the current claim should steer future runs:
|
||||
|
||||
- `high`: verified more than once or strongly evidenced by the current run
|
||||
- `medium`: verified once in a clean run and likely reusable
|
||||
- `low`: weak but still useful signal; prefer as a hint, not as a default assumption
|
||||
|
||||
Use `evidence` as a short operational reason for why the claim currently deserves to exist. Keep it concise. It is not a transcript.
|
||||
|
||||
## Required Sections
|
||||
|
||||
Every domain note should contain these sections:
|
||||
|
||||
```markdown
|
||||
## Platform traits
|
||||
|
||||
Facts about architecture, login behavior, routing, rendering, anti-automation friction, or content loading.
|
||||
|
||||
## Effective patterns
|
||||
|
||||
Verified URL shapes, interaction strategies, selectors, or browser workflows that reliably work.
|
||||
|
||||
## Known pitfalls
|
||||
|
||||
Things that fail, and why they fail.
|
||||
```
|
||||
|
||||
Keep each point concrete and operational.
|
||||
|
||||
## End-of-Run Review
|
||||
|
||||
Every browser run that touches a domain should end with one quick question:
|
||||
|
||||
> Did this run verify a reusable fact, disprove a stored fact, or teach nothing domain-specific?
|
||||
|
||||
Use that answer to decide whether to create, update, downgrade, or leave the note alone.
|
||||
|
||||
If the run taught nothing reusable, do not force a note.
|
||||
|
||||
## Update Discipline
|
||||
|
||||
Treat the note as a reusable operating aid, not as a scratchpad.
|
||||
|
||||
- Add only reusable facts.
|
||||
- Rewrite vague notes into clear operational statements.
|
||||
- Remove or replace claims that later evidence disproves.
|
||||
- Treat discovery dates as context markers, not guarantees that the behavior still works unchanged.
|
||||
- If a stored pattern fails under comparable conditions, stop retrying it as if it were still true. Fall back to the generic workflow, then downgrade confidence, rewrite the claim, or delete it.
|
||||
- Prefer one atomic fact per bullet. Future runs should be able to keep, rewrite, or remove one claim without touching unrelated claims.
|
||||
|
||||
If a note exists for the active domain, read it before operating on the site.
|
||||
@@ -0,0 +1,149 @@
|
||||
# Task Routing
|
||||
|
||||
This reference decides whether the task should stay on a static retrieval path or escalate into live browser work. It is about evidence quality and route selection, not page-operation mechanics.
|
||||
|
||||
## Goal-first routing
|
||||
|
||||
Start every task by answering two questions:
|
||||
|
||||
1. What outcome are we trying to produce?
|
||||
2. What evidence would prove that outcome?
|
||||
|
||||
That framing should decide the route. Do not start from "which tool do I want to use?" Start from "what would count as done?"
|
||||
|
||||
Good examples:
|
||||
|
||||
- "Extract the page title and canonical URL from a known public page" is a static retrieval task.
|
||||
- "Confirm whether the logged-in settings page still shows the new toggle after saving" is a live browser task.
|
||||
- "Download the media source if it is exposed in the DOM, otherwise inspect the rendered video state" starts as media-aware routing and may escalate into browser plus media inspection.
|
||||
|
||||
Each step should produce evidence that moves the task closer to done. If the current route stops improving the evidence, change the route instead of retrying the same tactic. Escalate when needed, but do not downgrade a task that has already been classified as `browser-required`.
|
||||
|
||||
## Static vs live browser decision
|
||||
|
||||
Default to direct retrieval when browser state is not the point.
|
||||
|
||||
Use this quick routing table when the task shape is still ambiguous:
|
||||
|
||||
| Scenario | Tool |
|
||||
| --------------------------------------------------------------------------------- | ------------------ |
|
||||
| Search snippets or keyword results to discover likely sources | Web search |
|
||||
| The URL is known and you want targeted information extracted from the page | Page retrieval |
|
||||
| The URL is known and you need raw HTML such as `meta` tags or JSON-LD | `curl` |
|
||||
| The task depends on login state, rendered UI, or free-form in-browser exploration | Live browser stack |
|
||||
| The site defeats static access methods or requires rendered-state inspection | Live browser stack |
|
||||
|
||||
Stay on the static path when:
|
||||
|
||||
- you already know the URL
|
||||
- you need text, metadata, raw HTML, structured tags, or a small deterministic field set
|
||||
- the task does not depend on login state, rendered interaction, gestures, or visible confirmation
|
||||
- a browser action would only repeat what page retrieval or `curl` can already prove
|
||||
|
||||
Escalate to live browser work when:
|
||||
|
||||
- rendered state is itself the evidence
|
||||
- the site requires login state, route transitions, expansion, hover, upload, or keyboard interaction
|
||||
- the next step is easier to discover from the page than from URL guesswork
|
||||
- static retrieval stops improving the answer and the remaining uncertainty is in the browser UI
|
||||
|
||||
Use this escalation ladder:
|
||||
|
||||
1. Try the cheapest direct retrieval path first.
|
||||
2. Extract only the fields you actually need.
|
||||
3. Escalate into the browser once visible state, session state, or interaction becomes the missing evidence.
|
||||
|
||||
The browser is not a purity prize. It is the right tool once the cheaper route no longer answers the real question.
|
||||
|
||||
The live browser path does not require a known URL. You can start from whatever entry point is available and navigate through the page itself by searching, clicking, and following links. Web search, page retrieval, and `curl` do not carry login state.
|
||||
|
||||
### Programmatic vs live browser modes
|
||||
|
||||
Programmatic access is usually faster when the target is already expressible as a stable URL plus a small extraction goal.
|
||||
|
||||
Live browser work is usually safer when the site expects a real page session and the next step is easier to discover through visible interaction than through URL construction.
|
||||
|
||||
Live browser work is also a probe. A small amount of real interaction can reveal:
|
||||
|
||||
- canonical links
|
||||
- redirect behavior
|
||||
- hidden parameters
|
||||
- actual route shape
|
||||
- UI-specific confirmation states
|
||||
|
||||
Once the page gives you a link, prefer that site-generated `href` over a hand-built URL. The DOM link is more likely to preserve routing details and required parameters.
|
||||
|
||||
## Static-first document and metadata retrieval
|
||||
|
||||
When the task is still on the static path:
|
||||
|
||||
1. Fetch the stable URL with the cheapest direct retrieval tool.
|
||||
2. Extract the small fixed field set you actually need, such as `og:title`, `og:type`, canonical metadata, or RFC title / number / publication date.
|
||||
3. Return to the browser only if visible confirmation is still needed, the page is client-generated, or the static response remains ambiguous.
|
||||
|
||||
## Login judgment
|
||||
|
||||
Do not escalate to user login just because a page looks restricted. First answer the operational question: can the target content or action already be reached from the current session?
|
||||
|
||||
Use this sequence:
|
||||
|
||||
1. Go to the most direct safe target you can inspect.
|
||||
2. Check whether the content or control is already visible or extractable.
|
||||
3. Continue without asking for login help if the task is already completable.
|
||||
4. Ask for login only when the task remains blocked and login is a plausible unlock for the specific missing content or action.
|
||||
|
||||
Current live browser sessions often already carry the needed authenticated state. Do not assume a fresh login is required until the target content remains blocked in the current session.
|
||||
|
||||
Good evidence that login is truly required:
|
||||
|
||||
- the page redirects to a login route instead of the target view
|
||||
- the content itself is missing behind an auth wall
|
||||
- the control you need has been replaced by a sign-in requirement
|
||||
- a verified domain note says the workflow depends on authenticated state
|
||||
|
||||
Be careful with false positives:
|
||||
|
||||
- a login modal does not always block DOM extraction
|
||||
- a site can look restricted while still exposing the needed links or metadata
|
||||
- "not found" can reflect the wrong route shape, missing parameters, or anti-automation behavior rather than true absence
|
||||
|
||||
When login is needed, say exactly what is blocked. The default wording is:
|
||||
|
||||
> "The current page is still unable to access [specific content] without login. Please sign in to [site name] in your current browser session, then tell me to continue."
|
||||
|
||||
After the user logs in, keep the existing workflow and continue with a refresh or a fresh task-owned page rather than rebuilding the whole browser setup from scratch.
|
||||
|
||||
## Primary-source verification
|
||||
|
||||
Verification means finding the most authoritative source that can actually support the claim. Search engines and aggregators help you discover candidates; they do not prove correctness on their own.
|
||||
|
||||
Prefer these source classes:
|
||||
|
||||
| Information type | Primary source |
|
||||
| ---------------------- | ----------------------------------------------------- |
|
||||
| Policy or regulation | The publishing authority's official site |
|
||||
| Company announcement | The company's newsroom or official announcement page |
|
||||
| Academic claim | The original paper or the institution's official page |
|
||||
| Tool behavior or usage | Official docs and source code |
|
||||
|
||||
Use repeated secondary reporting only as a discovery aid. Once you have a credible lead, go read the original text.
|
||||
|
||||
If the primary source cannot be located after reasonable effort:
|
||||
|
||||
- fall back to the most authoritative original secondary source you can find
|
||||
- say explicitly that the evidence is second-hand
|
||||
- say explicitly if the conclusion rests on a single non-official source
|
||||
|
||||
Useful wording:
|
||||
|
||||
> "I couldn't locate the official source. The following is based on [source], so it may contain transcription or interpretation error."
|
||||
|
||||
If only one non-official source supports the conclusion:
|
||||
|
||||
> "This conclusion currently rests on a single non-official source."
|
||||
|
||||
## Reference boundary
|
||||
|
||||
This file chooses the route. It should not become a second routing hub.
|
||||
|
||||
Once you know which route the task needs, return to [the skill entrypoint](../SKILL.md) and load the next reference from the entrypoint's loading guide. That keeps reference loading one level deep and makes the entrypoint the only place that fans out to other files.
|
||||
@@ -1,76 +0,0 @@
|
||||
# Tool Matrix
|
||||
|
||||
Use this table when deciding whether a task should stay on public-web tools, switch into the live browser session, or use a separate automation browser.
|
||||
|
||||
| Situation | Primary tool | Why | Avoid |
|
||||
| -------------------------------------------------------------------------------- | --------------------------------------------------------- | ----------------------------------------------------------------------------- | --------------------------------------------------------------- |
|
||||
| Public discovery, recent info, citation-backed answers | `web.search_query` plus `web.open` | Fast source discovery, easy citations, no browser intrusion | Attaching to the browser session just to read public pages |
|
||||
| Known public page where rendered state is not important | `web.open` or `web.find` | Cheapest read path | Launching browser tools before proving they are needed |
|
||||
| Known article, doc, or PDF where a cheaper processed read is enough | `web.open` or a markdown mirror such as Jina Reader | Good for content-first pages and lower token use | Jumping straight to a browser for article-shaped pages |
|
||||
| Need raw HTML, headers, JSON-LD, or source metadata | `shell_command` with a native fetch tool | Preserves the original response shape | Treating a processed read as if it were source HTML |
|
||||
| Task depends on current sign-in state, cookies, or app context | `chrome-devtools` | Reuses the live browser session | Playwright unless the user wants a separate clean state |
|
||||
| User already selected an element in Elements | `chrome-devtools.take_snapshot` then `evaluate_script` | Continues from the existing debugging context | Recreating the page in a new browser by default |
|
||||
| User already selected a request in Network | `chrome-devtools.get_network_request` | Reads the current request directly | Listing every request before checking the selected one |
|
||||
| Dynamic SPA, lazy loading, console errors, network timing, performance, uploads | `chrome-devtools` | Best coverage for live DOM, network, and performance evidence | Raw fetches that miss app state |
|
||||
| Social platform or anti-bot-heavy site where static fetches are weak | `chrome-devtools` | Lets the agent work through the real rendered page and session context | Assuming search results or static fetches reflect the real page |
|
||||
| Need a separate clean browser context or reproducible isolated automation | `playwright` | Best for isolated automation flows | Reusing the live session when state isolation is the goal |
|
||||
| Need a downloadable public asset after discovering the real URL in-page | `shell_command` with a native fetch tool | Better than screenshotting a file that is directly fetchable | Using screenshots for raw-fetch problems |
|
||||
| Need to inspect or compare several public sources | Batched `web` calls | Parallel and citation-friendly | Serial browser attachment for each source |
|
||||
| Need several independent local-doc or shell reads | `multi_tool_use.parallel` | Parallelizes developer-tool reads cleanly | Using it for `web` operations or dependent browser actions |
|
||||
| User explicitly asks for parallel agent work across independent browsing targets | Goal-driven delegated workers plus isolated page contexts | Keeps independent targets separated without disturbing one mutable page state | Splitting work that depends on one mutable page state |
|
||||
|
||||
## Decision Rules
|
||||
|
||||
### Start with `web` when
|
||||
|
||||
- The answer should cite public sources.
|
||||
- The page is not user-specific.
|
||||
- Search quality is more important than interaction.
|
||||
- The task can be solved from docs, blogs, release notes, or public pages.
|
||||
- The first problem is source discovery, not page interaction.
|
||||
|
||||
### Start with a processed read when
|
||||
|
||||
- The URL is known and the page is mostly article, documentation, or PDF content.
|
||||
- You want the page text, not its raw HTML.
|
||||
- Token efficiency matters and the page structure is not highly interactive.
|
||||
|
||||
### Start with `chrome-devtools` when
|
||||
|
||||
- The task depends on the user's current Chrome state.
|
||||
- The relevant element or request is already selected in DevTools.
|
||||
- The target is behind login or requires a current app session.
|
||||
- You need DOM, console, network, performance, upload, or rendered media from the real page.
|
||||
- The site is dynamic enough that static fetches are unreliable.
|
||||
|
||||
### Start with `playwright` when
|
||||
|
||||
- The user wants a clean, separate browser context.
|
||||
- The task is a browser automation workflow that should not touch the live session.
|
||||
- The environment does not have the needed Chrome DevTools session attached.
|
||||
|
||||
### Start with a raw fetch when
|
||||
|
||||
- You need HTML source, response headers, or direct file downloads.
|
||||
- Browser rendering is not the interesting part.
|
||||
- The task is about response bodies rather than in-page behavior.
|
||||
- You already discovered the exact asset or page URL and need its source form.
|
||||
|
||||
## Escalation Order
|
||||
|
||||
When the first layer fails, escalate thoughtfully:
|
||||
|
||||
1. `web`
|
||||
2. processed read
|
||||
3. raw fetch
|
||||
4. `chrome-devtools`
|
||||
5. `playwright`
|
||||
|
||||
This is not a rigid ladder. If the task is obviously logged-in or DevTools-driven from the start, begin with `chrome-devtools`.
|
||||
|
||||
## Notes
|
||||
|
||||
- `web` already supports batching multiple search or open requests in a single call.
|
||||
- `multi_tool_use.parallel` is only for developer tools, not the `web` namespace.
|
||||
- Do not use the live browser session when a public, lower-risk layer is already enough.
|
||||
- Prefer site-generated URLs over hand-constructed guesses when a page exposes the real link.
|
||||
Reference in new issue
Block a user